








dotNetRDF Toolkit for Windows
Hypermedia-driven API tests
PGSSoft/Nancy.ProblemDetails 2
Unified error responses for Nancy 1.x (RFC7807)
Do-It-Yourself CommandLine Interface for DbUp
Strona Fundacji Wroc.IT
hypermedia-app/api-testing-dsl 0
Hypermedia-style API testing DSL
FramApp - Polymer
tpluscode/all-implementations-of 0
Walks the prototype tree and find all method of given name
issue commentrdfjs/types
:+1: to atlassian changesets but they will make deployment more difficult to automate. I have never really tried their proposed GitHub Actions workflow
since this repo contains the types for 3 different specs, it'd be somewhat difficult if they were versioned separately.
And what if the 3 types packages were indeed 3 types packages.
@rdfjs/spec-data-model@rdfjs/spec-dataset@rdfjs/spec-stream
And then we can keep rdf-js to simply re-export for those above. Setting it up like this makes all the more sense to adopt changesets

comment created time in 5 hours
Pull request review commentzazuko/cube-creator
+import { RdfResourceCore } from '@tpluscode/rdfine/RdfResource'+import { Constructor, property } from '@tpluscode/rdfine'+import { Collection } from '@rdfine/hydra'+import { cc } from '@cube-creator/core/namespace'+import { Table } from './Table'+import { Link } from './lib/Link'+import { NamedNode } from 'rdf-js'+import { schema } from '@tpluscode/rdf-ns-builders'++export interface Job extends RdfResourceCore {+ tableCollection: Link<Collection<Table>>+ cubeGraph?: NamedNode+ label: string+}++export function JobMixin<Base extends Constructor>(base: Base) {+ class Impl extends base implements Job {+ @property.resource({ path: cc.tables })+ tableCollection!: Link<Collection<Table>>++ @property({ path: cc.cubeGraph })+ cubeGraph?: NamedNode++ @property.literal({ path: schema.label })+ label!: string
    label!: string

    @property.literal({ path: dcterms.created, type: Date })
    create!: Date

comment created time in 8 hours
push eventhypermedia-app/labyrinth
commit sha 2fca756c13f93b0f59065a5f07c94738b59f626d
feat: eager-loading collection member properties
commit sha e29155537d638b01dd2969b36c1a1124518d3685
fix: collection member assertions
push time in 9 hours
push eventhypermedia-app/labyrinth
commit sha 7a51354c0efd2a603fe468dd47aa9abbadc855d0
fix: collection member assertions
push time in 9 hours
push eventhypermedia-app/labyrinth
commit sha 78571656976353a64ebdd99ae5be6de193fc4187
fix: collection member assertions
push time in 9 hours
push eventhypermedia-app/labyrinth
commit sha ae1bd25942bbf32d288be7e76c6bcfa8e4636652
feat: eager-loading collection member properties
push time in 9 hours
push eventhypermedia-app/labyrinth
commit sha 0f217c21e1376bcbbf391130830c4584688d96f0
refactor: extract collection loading from handler
commit sha 7ef4e8c99d26e591aff2ed793b7c889d5c535b8b
buid(deps): update hydra-box
commit sha 6e4669a6faf9b135d822988be8face2a73bd7efb
chore: update types
push time in 9 hours
push eventhypermedia-app/labyrinth
commit sha cade07dcc0fb6650e0052ec310703cc1b119407f
chore: update types
push time in 9 hours
push eventhypermedia-app/labyrinth
commit sha 10517cb1439983c60b08cd357286070724df74a5
buid(deps): update hydra-box
push time in 9 hours
push eventtpluscode/settings-repository
commit sha 1e08d5005f489ec9708f8a130e6746bd71568e09
WS-2020.2.2 <[email protected] Update find.xml, web-types-registry.xml
push time in 12 hours
push eventzazuko/cube-creator
commit sha a4eb80bba5271aa548c4522a324aaca3734f3386
docs: data model of project, mapping, source
commit sha 94395fbe5613d6ac37ad5b20a6188bbad60d09ce
docs: data model of tables
commit sha dd640a44406229690869204e2eec3b3c1962fa9c
test: use new data see to run cli tests
push time in 13 hours
issue closedzazuko/cube-creator
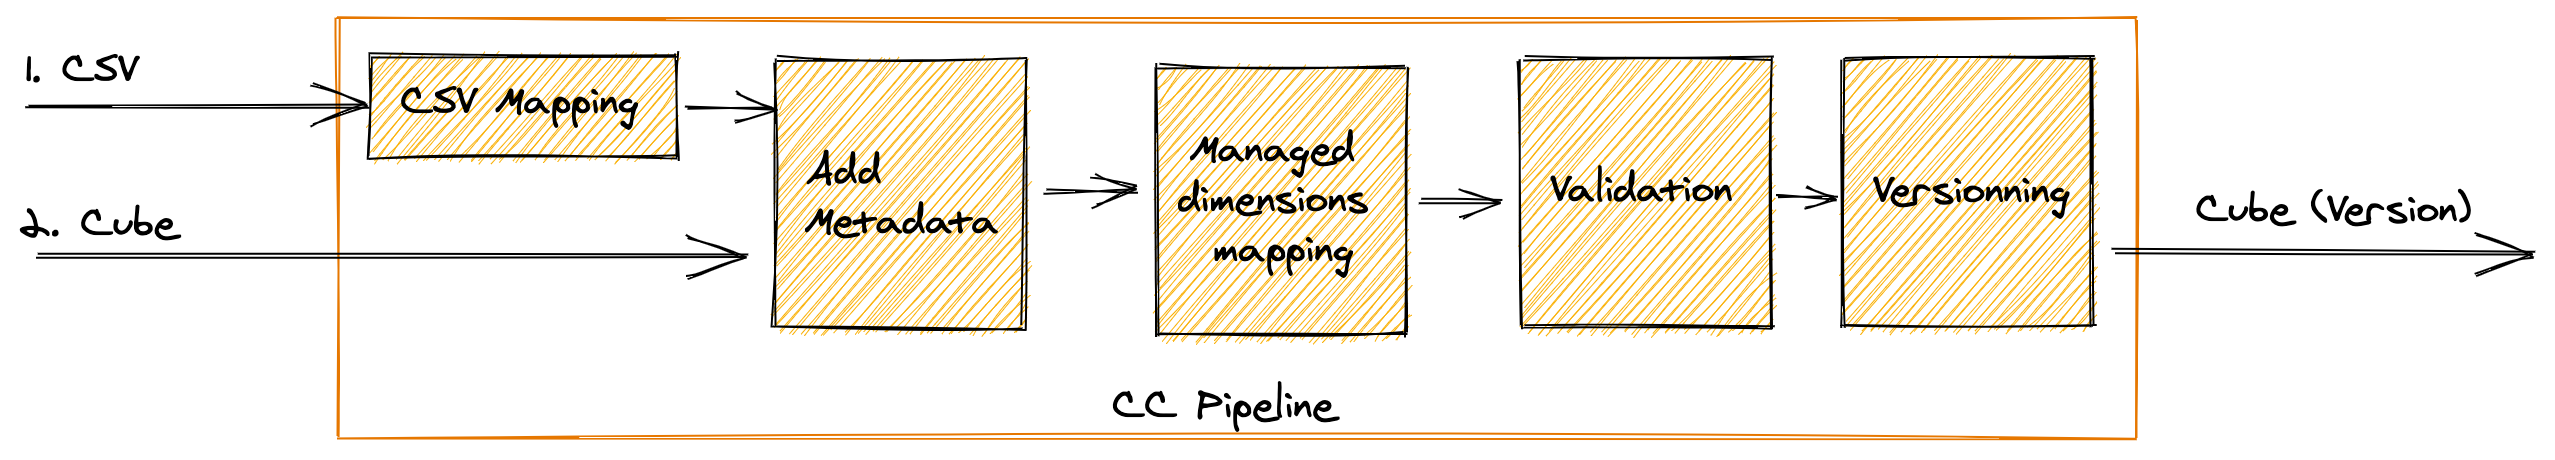
High-level overview of the application flow:
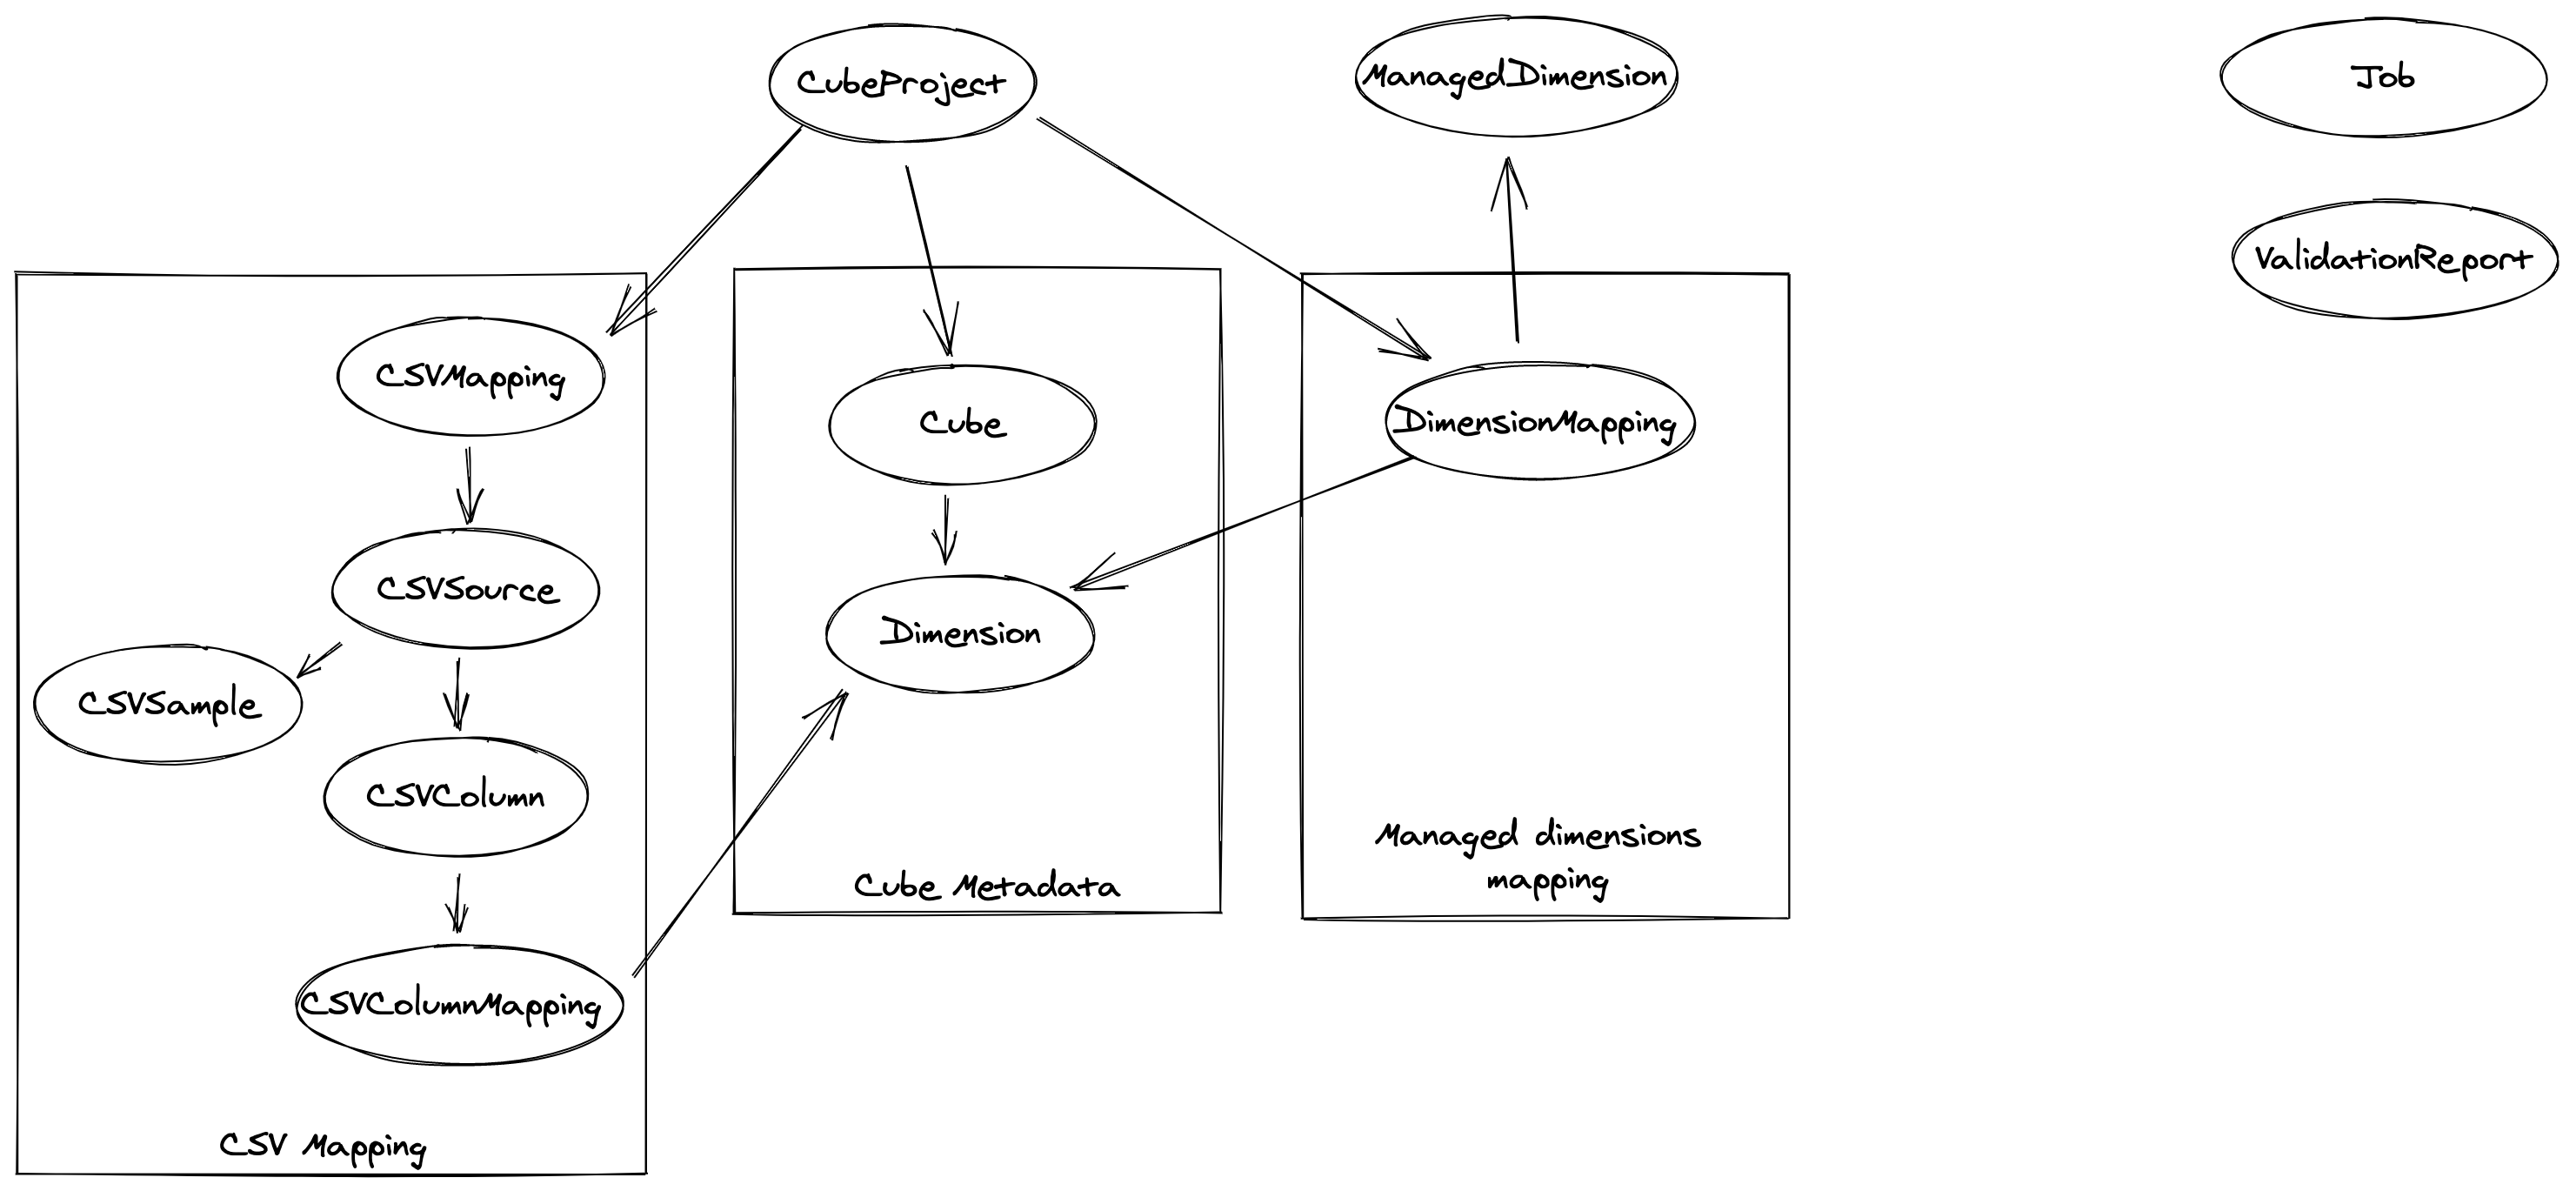
Raw data model (⚠️ outdated):
closed time in 13 hours
martinmaillard
issue commentzazuko/cube-creator
Integrate with GitLab for running transformation pipeline
Agree @lucafurrer 👌

comment created time in 14 hours
Pull request review commentzazuko/cube-creator
Create default column mappings for table
export async function createTable({ const table = await store .createMember(tableCollection.term, id.table(csvMapping.term, label.term.value)) + const csvSourceId = resource.out(cc.csvSource).term! as NamedNode+ const csvSource = await store.get(csvSourceId)+ table.addOut(rdf.type, cc.Table)- table.addOut(cc.csvSource, resource.out(cc.csvSource))+ table.addOut(cc.csvSource, csvSourceId) table.addOut(cc.csvMapping, csvMapping.term) table.addOut(schema.name, label) table.addOut(cc.identifierTemplate, resource.out(cc.identifierTemplate)) table.addOut(schema.color, resource.out(schema.color)) + // Create default column mappings for provided columns+ resource.out(csvw.column).terms+ .forEach((columnId) => {+ const column = csvSource.out(csvw.column).toArray()+ .find(({ term }) => term.equals(columnId))++ if (!column) {+ throw new Error(`Column ${columnId} not found`)+ }++ const columnName = column.out(schema.name).value!++ table.addOut(cc.columnMapping, id.columnMapping(table, columnName), (columnMapping) => {+ columnMapping+ .addOut(rdf.type, cc.ColumnMapping)+ .addOut(cc.sourceColumn, column)+ .addOut(cc.targetProperty, defaultProperty(columnName))
store.create returns a pointer to a new graph, an independent resource. Create it first; add values; attach only the ID to the table
      const columnMapping = store.create(id.columnMapping(table, columnName))
      columnMapping
        .addOut(rdf.type, cc.ColumnMapping)
        .addOut(cc.sourceColumn, column)
        .addOut(cc.targetProperty, defaultProperty(columnName))

      table.addOut(cc.columnMapping, columnMapping)
comment created time in 15 hours
Pull request review commentzazuko/cube-creator
+base <https://cube-creator.lndo.site/>+prefix schema: <http://schema.org/>+prefix dcterms: <http://purl.org/dc/terms/>+prefix rdf: <http://www.w3.org/1999/02/22-rdf-syntax-ns#>+prefix rdfs: <http://www.w3.org/2000/01/rdf-schema#>+prefix hydra: <http://www.w3.org/ns/hydra/core#>+prefix csvw: <http://www.w3.org/ns/csvw#>+prefix dtype: <http://www.linkedmodel.org/schema/dtype#>+prefix xsd: <http://www.w3.org/2001/XMLSchema#>+prefix void: <http://rdfs.org/ns/void#>+prefix cc: <https://cube-creator.zazuko.com/vocab#>++<ubd-example> a void:Dataset .
Yes.
comment created time in 15 hours
Pull request review commentzazuko/cube-creator
Create default column mappings for table
export async function createTable({ const table = await store .createMember(tableCollection.term, id.table(csvMapping.term, label.term.value)) + const csvSourceId = resource.out(cc.csvSource).term! as NamedNode+ const csvSource = await store.get(csvSourceId)+ table.addOut(rdf.type, cc.Table)- table.addOut(cc.csvSource, resource.out(cc.csvSource))+ table.addOut(cc.csvSource, csvSourceId) table.addOut(cc.csvMapping, csvMapping.term) table.addOut(schema.name, label) table.addOut(cc.identifierTemplate, resource.out(cc.identifierTemplate)) table.addOut(schema.color, resource.out(schema.color)) + // Create default column mappings for provided columns+ resource.out(csvw.column).terms+ .forEach((columnId) => {+ const column = csvSource.out(csvw.column).toArray()+ .find(({ term }) => term.equals(columnId))++ if (!column) {+ throw new Error(`Column ${columnId} not found`)+ }++ const columnName = column.out(schema.name).value!++ table.addOut(cc.columnMapping, id.columnMapping(table, columnName), (columnMapping) => {+ columnMapping+ .addOut(rdf.type, cc.ColumnMapping)+ .addOut(cc.sourceColumn, column)+ .addOut(cc.targetProperty, defaultProperty(columnName))
I propose the column mappings to be separate resources
comment created time in a day
Pull request review commentzazuko/cube-creator
Create default column mappings for table
+import { Resource } from 'alcaeus'+import { Term } from 'rdf-js'+import { Constructor } from '@tpluscode/rdfine'+import { Mixin } from '@tpluscode/rdfine/lib/ResourceFactory'+import * as ns from '@cube-creator/core/namespace'+import { ColumnMapping, CSVColumn } from '@/types'+import { commonActions } from '../common'++export default function mixin<Base extends Constructor<Resource>> (base: Base): Mixin {+ return class extends base implements ColumnMapping {+ get actions () {+ return commonActions(this)+ }++ get sourceColumn (): CSVColumn {+ return this.get<CSVColumn>(ns.cc.sourceColumn)+ }++ get targetProperty (): Term {+ return this.get(ns.cc.targetProperty).id+ }
This can be really simpler
    @property.resource({ path: ns.cc.sourceColumn })
    sourceColumn!: CSVColumn

    @property.resource({ path: ns.cc.targetProperty })
    targetProperty!: Term
comment created time in a day
Pull request review commentzazuko/cube-creator
Create default column mappings for table
export async function createTable({ const table = await store .createMember(tableCollection.term, id.table(csvMapping.term, label.term.value)) + const csvSourceId = resource.out(cc.csvSource).term! as NamedNode+ const csvSource = await store.get(csvSourceId)+ table.addOut(rdf.type, cc.Table)- table.addOut(cc.csvSource, resource.out(cc.csvSource))+ table.addOut(cc.csvSource, csvSourceId) table.addOut(cc.csvMapping, csvMapping.term) table.addOut(schema.name, label) table.addOut(cc.identifierTemplate, resource.out(cc.identifierTemplate)) table.addOut(schema.color, resource.out(schema.color)) + // Create default column mappings for provided columns+ resource.out(csvw.column).terms+ .forEach((columnId) => {+ const column = csvSource.out(csvw.column).toArray()+ .find(({ term }) => term.equals(columnId))++ if (!column) {+ throw new Error(`Column ${columnId} not found`)+ }++ const columnName = column.out(schema.name).value!++ table.addOut(cc.columnMapping, id.columnMapping(table, columnName), (columnMapping) => {+ columnMapping+ .addOut(rdf.type, cc.ColumnMapping)+ .addOut(cc.sourceColumn, column)+ .addOut(cc.targetProperty, defaultProperty(columnName))+ })+ })+ await store.save() return table }++function defaultProperty(columnName: string) {
Doesn't eslint complain that this function should be before createTable?
comment created time in a day
Pull request review commentzazuko/cube-creator
Create default column mappings for table
export async function createTable({ const table = await store .createMember(tableCollection.term, id.table(csvMapping.term, label.term.value)) + const csvSourceId = resource.out(cc.csvSource).term! as NamedNode+ const csvSource = await store.get(csvSourceId)+ table.addOut(rdf.type, cc.Table)- table.addOut(cc.csvSource, resource.out(cc.csvSource))+ table.addOut(cc.csvSource, csvSourceId) table.addOut(cc.csvMapping, csvMapping.term) table.addOut(schema.name, label) table.addOut(cc.identifierTemplate, resource.out(cc.identifierTemplate)) table.addOut(schema.color, resource.out(schema.color)) + // Create default column mappings for provided columns+ resource.out(csvw.column).terms+ .forEach((columnId) => {
You can directly loop over the pointers
  resource.out(csvw.column)
    .forEach(({ term: columnId }) => {
comment created time in a day
Pull request review commentzazuko/cube-creator
Create default column mappings for table
${shape('table/create')} { ${sh.order} 40 ; ${dash.editor} ${editor.ColorPicker} ; ] ;+ ${sh.property} [+ ${sh.name} "Columns to map" ;+ ${sh.path} ${csvw.column} ;+ ${sh.order} 50 ;+ ${dash.hidden} ${true} ;
Also, I'd propose at least
      ${dash.hidden} ${true} ;
      ${sh.nodeKind} ${sh.IRI} ;
comment created time in a day
Pull request review commentzazuko/cube-creator
Create default column mappings for table
export async function createTable({ const table = await store .createMember(tableCollection.term, id.table(csvMapping.term, label.term.value)) + const csvSourceId = resource.out(cc.csvSource).term! as NamedNode+ const csvSource = await store.get(csvSourceId)+ table.addOut(rdf.type, cc.Table)- table.addOut(cc.csvSource, resource.out(cc.csvSource))+ table.addOut(cc.csvSource, csvSourceId) table.addOut(cc.csvMapping, csvMapping.term) table.addOut(schema.name, label) table.addOut(cc.identifierTemplate, resource.out(cc.identifierTemplate)) table.addOut(schema.color, resource.out(schema.color)) + // Create default column mappings for provided columns+ resource.out(csvw.column).terms+ .forEach((columnId) => {+ const column = csvSource.out(csvw.column).toArray()+ .find(({ term }) => term.equals(columnId))++ if (!column) {+ throw new Error(`Column ${columnId} not found`)+ }++ const columnName = column.out(schema.name).value!++ table.addOut(cc.columnMapping, id.columnMapping(table, columnName), (columnMapping) => {+ columnMapping+ .addOut(rdf.type, cc.ColumnMapping)+ .addOut(cc.sourceColumn, column)+ .addOut(cc.targetProperty, defaultProperty(columnName))+ })+ })+ await store.save() return table }++function defaultProperty(columnName: string) {+ // TODO: How do we define the default target property for a column?+ return $rdf.namedNode(columnName)
Maybe some dummy NS like http://tempuri.org?
comment created time in a day
Pull request review commentzazuko/cube-creator
Create default column mappings for table
${shape('table/create')} { ${sh.order} 40 ; ${dash.editor} ${editor.ColorPicker} ; ] ;+ ${sh.property} [+ ${sh.name} "Columns to map" ;+ ${sh.path} ${csvw.column} ;+ ${sh.order} 50 ;+ ${dash.hidden} ${true} ;
You don't want to show UI for selecting columns when + is clicked?
comment created time in a day
Pull request review commentzazuko/cube-creator
+base <https://cube-creator.lndo.site/>+prefix schema: <http://schema.org/>+prefix dcterms: <http://purl.org/dc/terms/>+prefix rdf: <http://www.w3.org/1999/02/22-rdf-syntax-ns#>+prefix rdfs: <http://www.w3.org/2000/01/rdf-schema#>+prefix hydra: <http://www.w3.org/ns/hydra/core#>+prefix csvw: <http://www.w3.org/ns/csvw#>+prefix dtype: <http://www.linkedmodel.org/schema/dtype#>+prefix xsd: <http://www.w3.org/2001/XMLSchema#>+prefix void: <http://rdfs.org/ns/void#>+prefix cc: <https://cube-creator.zazuko.com/vocab#>++<ubd-example> a void:Dataset .++<cube-project/ubd> void:inDataset <ubd-example> .+graph <cube-project/ubd> {+ <cube-project/ubd>+ a cc:CubeProject, hydra:Resource ;+ cc:dataset <foen/ubd/28/pm1> ;+ cc:cube </cube/cli-test> ;+ cc:csvMapping <cube-project/ubd/csv-mapping> ;+ dcterms:creator <user> ;+ rdfs:label "UBD28 Project" ;+ .+}++<cube-project/ubd/csv-mapping> void:inDataset <ubd-example> .+graph <cube-project/ubd/csv-mapping> {+ <cube-project/ubd/csv-mapping>+ a cc:CsvMapping , hydra:Resource ;+ cc:csvSource <cube-project/ubd/csv-source/ubd> ;+ cc:csvSourceCollection <cube-project/ubd/csv-mapping/sources> ;+ cc:tables <cube-project/ubd/csv-mapping/tables> ;+ .+}++<cube-project/ubd/csv-mapping/sources> void:inDataset <ubd-example> .+graph <cube-project/ubd/csv-mapping/sources> {+ <cube-project/ubd/csv-mapping/sources>+ a cc:CSVSourceCollection , hydra:Collection ;+ hydra:manages [ hydra:object <cube-project/ubd/csv-mapping> ;+ hydra:property cc:csvMapping+ ] ;+ hydra:manages [ hydra:object cc:CSVSource ;+ hydra:property rdf:type+ ] ;+ hydra:title "CSV-Sources" ;+ cc:csvMapping <cube-project/ubd/csv-mapping> ;+ .+}++<cube-project/ubd/csv-source/ubd> void:inDataset <ubd-example> .+graph <cube-project/ubd/csv-source/ubd> {+ <cube-project/ubd/csv-source/ubd>+ a cc:CSVSource, hydra:Resource ;+ schema:associatedMedia [ a schema:MediaObject ;+ schema:contentUrl <http://s3:9000/cube-creator/test-data/ubd28/input_CH_yearly_air_immission_basetable.csv> ;+ schema:identifier "test-data/ubd28/input_CH_yearly_air_immission_basetable.csv";+ ] ;+ schema:name "ubd.csv" ;+ cc:csvMapping <cube-project/ubd/csv-mapping> ;+ csvw:dialect <cube-project/ubd/csv-source/ubd/dialect> ;+ csvw:column <cube-project/ubd/csv-source/ubd/column/year> ;+ csvw:column <cube-project/ubd/csv-source/ubd/column/station> ;+ csvw:column <cube-project/ubd/csv-source/ubd/column/value> ;+ csvw:column <cube-project/ubd/csv-source/ubd/column/aggregation> ;+ .++ <cube-project/ubd/csv-source/ubd/dialect>+ csvw:quoteChar "\"" ;+ csvw:delimiter "," ;+ csvw:header true ;+ .++ <cube-project/ubd/csv-source/ubd/column/year>+ a csvw:Column ;+ schema:name "YEAR" ;+ dtype:order 0 ;+ cc:csvColumnSample "2010" ;+ cc:csvColumnSample "2020" ;+ cc:csvColumnSample "2021" ;+ .++ <cube-project/ubd/csv-source/ubd/column/station>+ a csvw:Column ;+ schema:name "STATION" ;+ dtype:order 1 ;+ cc:csvColumnSample "1" ;+ cc:csvColumnSample "2" ;+ cc:csvColumnSample "3" ;+ .++ <cube-project/ubd/csv-source/ubd/column/value>+ a csvw:Column ;+ schema:name "VALUE" ;+ dtype:order 2 ;+ cc:csvColumnSample "3.4" ;+ cc:csvColumnSample "2.1" ;+ cc:csvColumnSample "2.9" ;+ .++ <cube-project/ubd/csv-source/ubd/column/aggregation>+ a csvw:Column ;+ schema:name "AGGREGATION" ;+ dtype:order 3 ;+ cc:csvColumnSample "13.4" ;+ cc:csvColumnSample "14.4" ;+ cc:csvColumnSample "18.0" ;+ .+}++<cube-project/ubd/csv-source/stations> void:inDataset <ubd-example> .+graph <cube-project/ubd/csv-source/stations> {+ <cube-project/ubd/csv-source/stations>+ a cc:CSVSource, hydra:Resource ;+ cc:csvMapping <cube-project/ubd/csv-mapping> ;+ schema:associatedMedia [ a schema:MediaObject ;+ schema:contentUrl <http://s3:9000/cube-creator/test-data/ubd28/input_CH_yearly_air_immission_basetable.csv> ;+ schema:identifier "test-data/ubd28/input_CH_yearly_air_immission_basetable.csv";+ ] ;+ schema:name "stations.csv" ;+ csvw:dialect <cube-project/ubd/csv-source/stations/dialect> ;+ csvw:column <cube-project/ubd/csv-source/ubd/column/year> ;+ csvw:column <cube-project/ubd/csv-source/stations/column/station-name-fr> ;+ csvw:column <cube-project/ubd/csv-source/stations/column/station-name-de> ;+ .++ <cube-project/ubd/csv-source/stations/dialect>+ csvw:quoteChar "\"" ;+ csvw:delimiter "," ;+ csvw:header true ;+ .++ <cube-project/ubd/csv-source/stations/column/station-id>+ a csvw:Column ;+ schema:name "STATION_ID" ;+ dtype:order 0 ;+ cc:csvColumnSample "1" ;+ cc:csvColumnSample "2" ;+ cc:csvColumnSample "3" ;+ .++ <cube-project/ubd/csv-source/stations/column/station-name-fr>+ a csvw:Column ;+ schema:name "STATION_NAME_FR" ;+ dtype:order 1 ;+ cc:csvColumnSample "ABC" ;+ cc:csvColumnSample "DEF" ;+ cc:csvColumnSample "GHI" ;+ .++ <cube-project/ubd/csv-source/stations/column/station-name-de>+ a csvw:Column ;+ schema:name "STATION_NAME_DE" ;+ dtype:order 2 ;+ cc:csvColumnSample "ABK" ;+ cc:csvColumnSample "DEF" ;+ cc:csvColumnSample "GHI" ;+ .+}++<cube-project/ubd/csv-mapping/tables> void:inDataset <ubd-example> .+graph <cube-project/ubd/csv-mapping/tables> {+ <cube-project/ubd/csv-mapping/tables>+ a cc:TableCollection, hydra:Collection ;+ hydra:title "Tables" ;+ hydra:manages [ hydra:property rdf:type ;+ hydra:object cc:Table+ ] ;+ hydra:manages [ hydra:property cc:csvMapping ;+ hydra:object <cube-project/ubd/csv-mapping>+ ] ;+ cc:csvMapping <cube-project/ubd/csv-mapping> ;+ .+}++<project/ubd/csv-mapping/table-observation> void:inDataset <ubd-example> .+graph <project/ubd/csv-mapping/table-observation> {+ <project/ubd/csv-mapping/table-observation>+ a cc:Table, cc:ObservationTable, hydra:Resource ;+ cc:csvw <project/ubd/csv-mapping/table-observation/csvw> ;
This is something which was missing from #10 but will be needed to get the pipeline running
comment created time in a day
Pull request review commentzazuko/cube-creator
@prefix dc: <http://purl.org/dc/elements/1.1/> . [] rdf:type fuseki:Server ;+ ja:context [ ja:cxtName "arq:queryTimeout" ; ja:cxtValue "10000,600000" ] ;
Increased timeout because the handler for CSV sample is painfully slow. cc @lucafurrer
comment created time in a day
Pull request review commentzazuko/cube-creator
+base <https://cube-creator.lndo.site/>+prefix schema: <http://schema.org/>+prefix dcterms: <http://purl.org/dc/terms/>+prefix rdf: <http://www.w3.org/1999/02/22-rdf-syntax-ns#>+prefix rdfs: <http://www.w3.org/2000/01/rdf-schema#>+prefix hydra: <http://www.w3.org/ns/hydra/core#>+prefix csvw: <http://www.w3.org/ns/csvw#>+prefix dtype: <http://www.linkedmodel.org/schema/dtype#>+prefix xsd: <http://www.w3.org/2001/XMLSchema#>+prefix void: <http://rdfs.org/ns/void#>+prefix cc: <https://cube-creator.zazuko.com/vocab#>++<ubd-example> a void:Dataset .++<cube-project/ubd> void:inDataset <ubd-example> .+graph <cube-project/ubd> {+ <cube-project/ubd>+ a cc:CubeProject, hydra:Resource ;+ cc:dataset <foen/ubd/28/pm1> ;+ cc:cube </cube/cli-test> ;+ cc:csvMapping <cube-project/ubd/csv-mapping> ;+ dcterms:creator <user> ;+ rdfs:label "UBD28 Project" ;+ .+}++<cube-project/ubd/csv-mapping> void:inDataset <ubd-example> .+graph <cube-project/ubd/csv-mapping> {+ <cube-project/ubd/csv-mapping>+ a cc:CsvMapping , hydra:Resource ;+ cc:csvSource <cube-project/ubd/csv-source/ubd> ;+ cc:csvSourceCollection <cube-project/ubd/csv-mapping/sources> ;+ cc:tables <cube-project/ubd/csv-mapping/tables> ;+ .+}++<cube-project/ubd/csv-mapping/sources> void:inDataset <ubd-example> .+graph <cube-project/ubd/csv-mapping/sources> {+ <cube-project/ubd/csv-mapping/sources>+ a cc:CSVSourceCollection , hydra:Collection ;+ hydra:manages [ hydra:object <cube-project/ubd/csv-mapping> ;+ hydra:property cc:csvMapping+ ] ;+ hydra:manages [ hydra:object cc:CSVSource ;+ hydra:property rdf:type+ ] ;+ hydra:title "CSV-Sources" ;+ cc:csvMapping <cube-project/ubd/csv-mapping> ;+ .+}++<cube-project/ubd/csv-source/ubd> void:inDataset <ubd-example> .+graph <cube-project/ubd/csv-source/ubd> {+ <cube-project/ubd/csv-source/ubd>+ a cc:CSVSource, hydra:Resource ;+ schema:associatedMedia [ a schema:MediaObject ;+ schema:contentUrl <http://s3:9000/cube-creator/test-data/ubd28/input_CH_yearly_air_immission_basetable.csv> ;+ schema:identifier "test-data/ubd28/input_CH_yearly_air_immission_basetable.csv";+ ] ;+ schema:name "ubd.csv" ;+ cc:csvMapping <cube-project/ubd/csv-mapping> ;+ csvw:dialect <cube-project/ubd/csv-source/ubd/dialect> ;+ csvw:column <cube-project/ubd/csv-source/ubd/column/year> ;+ csvw:column <cube-project/ubd/csv-source/ubd/column/station> ;+ csvw:column <cube-project/ubd/csv-source/ubd/column/value> ;+ csvw:column <cube-project/ubd/csv-source/ubd/column/aggregation> ;+ .++ <cube-project/ubd/csv-source/ubd/dialect>+ csvw:quoteChar "\"" ;+ csvw:delimiter "," ;+ csvw:header true ;+ .++ <cube-project/ubd/csv-source/ubd/column/year>+ a csvw:Column ;+ schema:name "YEAR" ;+ dtype:order 0 ;+ cc:csvColumnSample "2010" ;+ cc:csvColumnSample "2020" ;+ cc:csvColumnSample "2021" ;+ .++ <cube-project/ubd/csv-source/ubd/column/station>+ a csvw:Column ;+ schema:name "STATION" ;+ dtype:order 1 ;+ cc:csvColumnSample "1" ;+ cc:csvColumnSample "2" ;+ cc:csvColumnSample "3" ;+ .++ <cube-project/ubd/csv-source/ubd/column/value>+ a csvw:Column ;+ schema:name "VALUE" ;+ dtype:order 2 ;+ cc:csvColumnSample "3.4" ;+ cc:csvColumnSample "2.1" ;+ cc:csvColumnSample "2.9" ;+ .++ <cube-project/ubd/csv-source/ubd/column/aggregation>+ a csvw:Column ;+ schema:name "AGGREGATION" ;+ dtype:order 3 ;+ cc:csvColumnSample "13.4" ;+ cc:csvColumnSample "14.4" ;+ cc:csvColumnSample "18.0" ;+ .+}++<cube-project/ubd/csv-source/stations> void:inDataset <ubd-example> .+graph <cube-project/ubd/csv-source/stations> {+ <cube-project/ubd/csv-source/stations>+ a cc:CSVSource, hydra:Resource ;+ cc:csvMapping <cube-project/ubd/csv-mapping> ;+ schema:associatedMedia [ a schema:MediaObject ;+ schema:contentUrl <http://s3:9000/cube-creator/test-data/ubd28/input_CH_yearly_air_immission_basetable.csv> ;+ schema:identifier "test-data/ubd28/input_CH_yearly_air_immission_basetable.csv";+ ] ;+ schema:name "stations.csv" ;+ csvw:dialect <cube-project/ubd/csv-source/stations/dialect> ;+ csvw:column <cube-project/ubd/csv-source/ubd/column/year> ;+ csvw:column <cube-project/ubd/csv-source/stations/column/station-name-fr> ;+ csvw:column <cube-project/ubd/csv-source/stations/column/station-name-de> ;+ .++ <cube-project/ubd/csv-source/stations/dialect>+ csvw:quoteChar "\"" ;+ csvw:delimiter "," ;+ csvw:header true ;+ .++ <cube-project/ubd/csv-source/stations/column/station-id>+ a csvw:Column ;+ schema:name "STATION_ID" ;+ dtype:order 0 ;+ cc:csvColumnSample "1" ;+ cc:csvColumnSample "2" ;+ cc:csvColumnSample "3" ;+ .++ <cube-project/ubd/csv-source/stations/column/station-name-fr>+ a csvw:Column ;+ schema:name "STATION_NAME_FR" ;+ dtype:order 1 ;+ cc:csvColumnSample "ABC" ;+ cc:csvColumnSample "DEF" ;+ cc:csvColumnSample "GHI" ;+ .++ <cube-project/ubd/csv-source/stations/column/station-name-de>+ a csvw:Column ;+ schema:name "STATION_NAME_DE" ;+ dtype:order 2 ;+ cc:csvColumnSample "ABK" ;+ cc:csvColumnSample "DEF" ;+ cc:csvColumnSample "GHI" ;+ .+}++<cube-project/ubd/csv-mapping/tables> void:inDataset <ubd-example> .+graph <cube-project/ubd/csv-mapping/tables> {+ <cube-project/ubd/csv-mapping/tables>+ a cc:TableCollection, hydra:Collection ;+ hydra:title "Tables" ;+ hydra:manages [ hydra:property rdf:type ;+ hydra:object cc:Table+ ] ;+ hydra:manages [ hydra:property cc:csvMapping ;+ hydra:object <cube-project/ubd/csv-mapping>+ ] ;+ cc:csvMapping <cube-project/ubd/csv-mapping> ;+ .+}++<project/ubd/csv-mapping/table-observation> void:inDataset <ubd-example> .+graph <project/ubd/csv-mapping/table-observation> {+ <project/ubd/csv-mapping/table-observation>+ a cc:Table, cc:ObservationTable, hydra:Resource ;+ cc:csvw <project/ubd/csv-mapping/table-observation/csvw> ;+ cc:csvMapping <cube-project/ubd/csv-mapping> ;+ cc:csvSource <cube-project/ubd/csv-source/ubd> ;+ schema:name "Observations" ;+ schema:color "#AAAAAA" ;+ cc:identifierTemplate "ammonia/observation/{STATION}-{YEAR}-annualmean" ;+ cc:columnMapping <project/ubd/csv-mapping/table-observation/column-mapping-1> ;+ cc:columnMapping <project/ubd/csv-mapping/table-observation/column-mapping-2> ;+ cc:columnMapping <project/ubd/csv-mapping/table-observation/column-mapping-3> ;+ cc:columnMapping <project/ubd/csv-mapping/table-observation/column-mapping-4> ;+ .+}++<project/ubd/csv-mapping/table-observation/column-mapping-1> void:inDataset <ubd-example> .+graph <project/ubd/csv-mapping/table-observation/column-mapping-1> {+ <project/ubd/csv-mapping/table-observation/column-mapping-1> a cc:ColumnMapping ;+ cc:sourceColumn <cube-project/ubd/csv-source/ubd/column/year> ;+ cc:targetProperty <dimension/year> ;+ cc:datatype xsd:gYear ;+ # -- Other possible ColumnMapping properties+ # cc:language+ # cc:default+ # cc:datatype/params TBD+ .+}++<table-observation/column-mapping-2> void:inDataset <ubd-example> .+graph <table-observation/column-mapping-2> {+ <table-observation/column-mapping-2> a cc:ColumnMapping ;+ cc:sourceColumn <cube-project/ubd/csv-source/ubd/column/station> ;+ cc:targetProperty <station> ;
@martinmaillard I'm a little unsure about these relative property URIs as they are based in the app URI
comment created time in a day
Pull request review commentzazuko/cube-creator
+base <https://cube-creator.lndo.site/>+prefix schema: <http://schema.org/>+prefix dcterms: <http://purl.org/dc/terms/>+prefix rdf: <http://www.w3.org/1999/02/22-rdf-syntax-ns#>+prefix rdfs: <http://www.w3.org/2000/01/rdf-schema#>+prefix hydra: <http://www.w3.org/ns/hydra/core#>+prefix csvw: <http://www.w3.org/ns/csvw#>+prefix dtype: <http://www.linkedmodel.org/schema/dtype#>+prefix xsd: <http://www.w3.org/2001/XMLSchema#>+prefix void: <http://rdfs.org/ns/void#>+prefix cc: <https://cube-creator.zazuko.com/vocab#>++<ubd-example> a void:Dataset .++<cube-project/ubd> void:inDataset <ubd-example> .+graph <cube-project/ubd> {+ <cube-project/ubd>+ a cc:CubeProject, hydra:Resource ;+ cc:dataset <foen/ubd/28/pm1> ;+ cc:cube </cube/cli-test> ;
As per #107, this would become cc:cubeGraph
comment created time in a day
Pull request review commentzazuko/cube-creator
+base <https://cube-creator.lndo.site/>+prefix schema: <http://schema.org/>+prefix dcterms: <http://purl.org/dc/terms/>+prefix rdf: <http://www.w3.org/1999/02/22-rdf-syntax-ns#>+prefix rdfs: <http://www.w3.org/2000/01/rdf-schema#>+prefix hydra: <http://www.w3.org/ns/hydra/core#>+prefix csvw: <http://www.w3.org/ns/csvw#>+prefix dtype: <http://www.linkedmodel.org/schema/dtype#>+prefix xsd: <http://www.w3.org/2001/XMLSchema#>+prefix void: <http://rdfs.org/ns/void#>+prefix cc: <https://cube-creator.zazuko.com/vocab#>++<ubd-example> a void:Dataset .
Group all graphs in a void:Dataset to easily purge those graphs when re-inserting seed data
comment created time in a day
Pull request review commentzazuko/cube-creator
"scripts": { "lint": "eslint . --ext .ts,.vue,.tsx --quiet --ignore-path .gitignore", "test": "mocha --recursive apis/**/*.test.ts",- "test:cli": "mocha --recursive cli/**/*.test.ts"+ "test:cli": "mocha --recursive cli/**/*.test.ts",+ "seed-data": "dotenv -e .local.env -- bash -c \"ts-node packages/testing/index.ts -i fuseki/sample-ubd.trig\""
Run yarn seed-data to populate Fuseki. Also possible from code as can be found in the cli package
comment created time in a day
Pull request review commentzazuko/cube-creator
feat: produce cube using new schema from the pipeline
code:link <node:barnard59-base#filter> ] ; code:arguments ( [ code:link <file:../lib/output-filter#removeCsvwTriples> ; a code:EcmaScript ] ) .++<#toDataset> a :Step;+ code:implementedBy [ a code:EcmaScript;+ code:link <node:rdf-stream-to-dataset-stream/bySubject.js>+ ] .++<#toObservation> a :Step;+ code:implementedBy [ a code:EcmaScript;+ code:link <node:barnard59-rdf/cube.js#toObservation>+ ] ;+ code:arguments [+ code:name "observer";+ code:value "https://ld.stadt-zuerich.ch/"+ ], [+ code:name "observations";+ code:value [+ a code:EcmaScript ;+ code:link <file:../lib/cube#getObservationSetId>+ ]++ ], [+ code:name "observation";+ code:value "({ dataset, observations }) => ([...dataset][0].subject)"^^code:EcmaScript+ ] .
This is the key part of the new pipeline steps.
The observation parameter simply uses the generated aboutUrl from csvw as the observation URI
The observations parameter is code to generate the cube:observationSet URI. I propose that the CSVW would implicitly add a mapping to output a cc:cube property. The cube:observationSet would simply be ${cubeId}/observation/
comment created time in a day
Pull request review commentzazuko/cube-creator
feat: produce cube using new schema from the pipeline
export const insertTestData = async () => { </project/cli-test> a ${hydra.Resource} , ${cc.CubeProject} ; ${cc.csvMapping} </project/cli-test/mapping> ;- ${cc.cube} </cube/cli-test>+ ${cc.cubeGraph} </cube/cli-test>
I propose a cc:cubeGraph property on project to explicitly prepare the location for generated triples
comment created time in a day
issue openedzazuko/cube-creator
We'll also need to add a `${table} cc:csvw <${table.id}/csvw>` triple here for the generated CSVW
We'll also need to add a ${table} cc:csvw <${table.id}/csvw> triple here for the generated CSVW
Originally posted by @tpluscode in https://github.com/zazuko/cube-creator/pull/87#discussion_r513569171
created time in a day
push eventzazuko/cube-creator
commit sha 7acf3de2cc66daa57c6cf4c3cd88f005dbaefa43
refactor: move editor namespace in cube-creator/core
commit sha 93260b4a255277b52411c12f9e2682daf1e0c1c1
feat: add color picker component
commit sha d79c3ce4089eaa43367ad67ee9a9c52b5648d1b8
feat: unfinished table creation form
commit sha 76932f8ed0e1c710fb91330abe766c1164895a1c
refactor: improve source mapping component
commit sha 09e2065be047fd8a69207a7d5f970fa3360ecb92
feat: only show table creation button if operation is there
commit sha 9dfea4d8987dd840ad83b5eac067e4c8a625c7f6
feat: use collection resource to populate dash:InstancesSelectEditor
commit sha 6035ccaf2cd81f7d14c5730fddc56627ff2a5bcd
style: fix eslint
commit sha 2574639e67be97822df6f3775235d94563df882b
fix: missing binding for default value
commit sha a745d1103ba8cce1ab519194948b153c43a30ff4
feat: create empty column mappings for selected columns
commit sha ffa5400513abbaafd5f824becf684cbf80f5a35e
feat: refresh table collection after creation
commit sha 3f34b7b236d3020ca594bb857cdc422d524a404e
Merge branch 'master' into feat/create-table
commit sha 47f865a63e6691353308b9b9b23a1d62ba24c05e
Merge branch 'master' into feat/create-table
commit sha c35b286f19b5bb1fdb21ebb6e8b3d3f5c56cee5f
feat: improve table display
commit sha 35e503a9584febda2c40320973ef88c3963283aa
feat(table): add endpoint to create a table
commit sha 3a789bc8e7d8d6c53bd9542b509a909a852f6127
test(table): create table e2e test
commit sha cdb9d4d9e639fcd3bbef20ba880a3e9971728231
Merge pull request #96 from zazuko/feat/api-create-table
commit sha 28733d148966c319809876c18a7c17ce27e3d7a9
Merge branch 'master' into feat/create-table
commit sha ccd087492936b17abe8d261f4c576f0ae61ed9d6
fix(ui): display success message on table creation
commit sha 812cd1a50d3466fe13f896be04d89357832e9b8c
chore(ui): remove half-done table column mapping
commit sha 057ba526fd03157f6a8dfd3034082af53386c69c
Merge pull request #87 from zazuko/feat/create-table Create table
push time in a day
PR merged zazuko/cube-creator
Missing things:
- [x] Table creation handler (#92)
- [x] A way to select the source (we don't have a component to show a select box yet)
pr closed time in a day
push eventzazuko/cube-creator
commit sha c6d2660c356e27ce9c4a37e4906bb198521aab08
docs: data model of project, mapping, source
commit sha 3ef20536cb7f9c1bc35c1cef3d910326e46f4a02
docs: data model of tables
commit sha 3eccc15eff8743156928c6bff79dfa57ba6d463a
test: use new data see to run cli tests
push time in a day
issue commentzazuko/cube-creator
Integrate with GitLab for running transformation pipeline
In fact, for the Job resource I propose a structure like
graph <csv-mapping/jobs/xyz> {
  <csv-mapping/jobs/xyz> a cc:Job ;
    cc:csvw <table-1/csvw> , <table-2/csvw> , <table-3/csvw> ;
    cc:cubeGraph <from-project>
}
cc:csvw would be a property of Table
xyz could be a short string like generated by nanoid
comment created time in a day
Pull request review commentzazuko/cube-creator
+import { GraphPointer } from 'clownface'+import { schema, rdf } from '@tpluscode/rdf-ns-builders'+import { cc } from '@cube-creator/core/namespace'+import { ResourceStore } from '../../ResourceStore'+import * as id from '../identifiers'+import { resourceStore } from '../resources'+import { NamedNode } from 'rdf-js'++interface CreateTableCommand {+ tableCollection: GraphPointer<NamedNode>+ resource: GraphPointer+ store?: ResourceStore+}++export async function createTable({+ tableCollection,+ resource,+ store = resourceStore(),+}: CreateTableCommand): Promise<GraphPointer> {+ const label = resource.out(schema.name)+ if (!label?.term) {+ throw new Error('schema:name missing from the payload')+ }++ const csvMapping = tableCollection.out(cc.csvMapping)+ if (!csvMapping?.term) {+ throw new Error('cc:csvMapping missing from the payload')+ }++ const table = await store+ .createMember(tableCollection.term, id.table(csvMapping.term, label.term.value))++ table.addOut(rdf.type, cc.Table)+ table.addOut(cc.csvSource, resource.out(cc.csvSource))+ table.addOut(cc.csvMapping, csvMapping.term)+ table.addOut(schema.name, label)+ table.addOut(cc.identifierTemplate, resource.out(cc.identifierTemplate))+ table.addOut(schema.color, resource.out(schema.color))
We'll also need to add a ${table} cc:csvw <${table.id}/csvw> triple here for the generated CSVW
comment created time in a day
issue commentzazuko/cube-creator
Integrate with GitLab for running transformation pipeline
The "trigger button" does not really provide any information.
The tables you'd get from the table collection <csv-mapper> cc:tables <csv-mapper/tables>
The target graph you'd get from the project <project> cc:cubeGraph <whatever>
comment created time in a day
push eventzazuko/cube-creator
commit sha 08e15cae84c72b9a4a3f6735ae87850db12bc9e5
feat: structure for delete project
commit sha 20357dd8ab6632ae7f6354dc4ec31293df47f735
Merge branch 'master' into feat/delete-project
commit sha 245d4349016bb9da096d91a740dd79df77851339
feat: delete sources when deleting project
commit sha 9513955e017d51574c53b8367ef0f679672247b8
test: delete project e2e
commit sha 3db316f28e78e694e47081df500abaa36911c1aa
refactor: extract delete mapping in own module
commit sha c3938cd4c4992016f3bfdfc305c3332203171737
chore: lint
commit sha 90167e69fe7106a8f4996551c39fc8b7f9867937
fix: delete source collection fix: correct casting in stream read for csv sources
commit sha 4a220fc469508f5a543d11979b1502264f2a389b
fix: use schema:DeleteAction instead of custom command
commit sha 0ea4b05dd21b4fe66059ce7dafb43de4f15cc41d
feat: delete cc:tables when project is deleted
commit sha 4f83abee0a9a0a6aba592761eec37b0dd5e0bfda
Merge branch 'master' into feat/delete-project
commit sha d21b25f59626bb04ec1d63cc45b4af83fa198358
fix: use schema:CreateAction
commit sha d05cdf6440ef586e8b4a17ad552b8da55cec77ec
fix: no body no validate Co-authored-by: Tomasz Pluskiewicz <[email protected]>
commit sha 620c64f4773bc0cea9aba28c06a8692c20219b54
refactor: CSVSources from store instead of query
commit sha dd9e3e81a91669ccd972cdfaeeaa8d9d117136ea
Merge pull request #94 from zazuko/feat/delete-project feat: delete project
push time in a day
PR merged zazuko/cube-creator

Make it possible to delete a projet
Deletes the project and the linked csvMapping as well as all linked csvSources
Linked to #88
pr closed time in a day
push eventzazuko/cube-creator
commit sha b41e38a3e7f2ac29578ba346790dd50b8028b579
fix(ui): avoid broken form submit behavior By default, shaperone wraps a focus node fieldset in a `<form>` tag, which prevents us from controlling the submit behavior of the form. It makes things like "hitting enter" behave in an unexpected way.
commit sha a4a5264dcd7de0d39c397a2a9c5c68d13a1d64a0
chore(ui): remove unused import
push time in a day
PR merged zazuko/cube-creator
By default, shaperone wraps a focus node fieldset in a <form> tag, which makes it impossible to control the behavior of the form. I just replaced the default renderer with a custom one without the form tag.
pr closed time in a day
pull request commentzazuko/cube-creator
Curious, what is the weird behavior? @martinmaillard
comment created time in a day
Pull request review commentzazuko/cube-creator
++import { NamedNode } from 'rdf-js'+import { ResourceStore } from '../../ResourceStore'+import { getSourcesFromMapping } from '../queries/csv-source'++import { deleteSourceWithoutSave } from '../csv-source/delete'+import { cc } from '@cube-creator/core/namespace'++export async function deleteMapping(csvMapping: NamedNode, store: ResourceStore): Promise<void> {+ const sources = await getSourcesFromMapping(csvMapping)+ for (const source of sources) {+ await deleteSourceWithoutSave(source, store)+ }
But besides, why not using the store?
  const csvMappingResource = await store.get(csvMapping)
  const sources = csvMappingResource.out(cc.csvSource).terms
  for await (const source of sources) {
    if (source.termType === 'NamedNode') {
      await deleteSource({resource: source, store})
    }
  }
comment created time in a day
Pull request review commentzazuko/cube-creator
export async function sourceWithFilenameExists(csvMapping: NamedNode, fileName: ` .execute(client.query) }++export async function getSourcesFromMapping(csvMapping: NamedNode, client = streamClient): Promise<any> {+ const stream = await SELECT.DISTINCT`?source`+ .WHERE` + GRAPH ${csvMapping}+ {+ ${csvMapping} ${cc.csvSource} ?source+ }+ `+ .execute(client.query)++ return new Promise((resolve, reject) => {+ const sources: string[] = []++ stream.on('data', row => {+ Object.entries(row).forEach(([, value]) => {+ if (value) {+ sources.push(value as string)+ }+ })+ })++ stream.on('end', () => resolve(sources))+ stream.on('error', error => reject(error))+ })+}
This can be much simpler with a parsingClient (also exported from ../../query-client)
export async function * getSourcesFromMapping(csvMapping: NamedNode, client = parsingClient) {
  const results = await SELECT.DISTINCT`?source`
    .WHERE`
    GRAPH ${csvMapping}
    {
      ${csvMapping} ${cc.csvSource} ?source
    }
    `
    .execute(client.query)

  for (const result of results) {
    const source = result.source
    if (source.termType === 'NamedNode') {
      yield source
    }
  }
}
comment created time in a day
Pull request review commentzazuko/cube-creator
export const post = protectedResource( await res.dataset(project.dataset) }), )++export const remove = protectedResource(+ shaclValidate,
No body, no validation :)
comment created time in a day
Pull request review commentzazuko/hydra-box
failing cases for property operations
function factory ({ loader }) { return async (req, res, next) => { let resources = await loader.forClassOperation(req.hydra.term) + if (resources.length > 1) {+ return next(new Error(`no unique resource found for: <${req.hydra.term.value}>`))+ }
This check is moved up because only "multiple class resources" are an issue.
Multiple candidates for property operation can still be reconciled
comment created time in 2 days
Pull request review commentzazuko/hydra-box
failing cases for property operations
function findPropertyOperations ({ types, method, term, resource }) { return operations } -function factory (api) {- return async (req, res, next) => {- if (!req.hydra.resource) {- return next()- }+function findPropertyOperations ({ term, resourceCandidates, api, method }) {+ const apiGraph = clownface(api) - const method = req.method === 'HEAD' ? 'GET' : req.method- const types = clownface({ ...api, term: [...req.hydra.resource.types] })+ return resourceCandidates+ .reduce((matched, resource) => {+ const types = apiGraph.node([...resource.types]) - let operations- if (req.hydra.term.equals(req.hydra.resource.term)) {- // only look for direct operation when the root resource is requested- operations = findClassOperations(types, method)- }- if (!operations) {- // otherwise try finding the operation by property usage- operations = findPropertyOperations({ types, method, term: req.hydra.term, resource: req.hydra.resource })- }+ const more = findCandidatePropertyOperations({ types, method, term, resource })++ if (!matched) {+ return more+ }++ if (more.terms.length === 0) {+ return matched+ } - const [operation, ...rest] = (operations || []).toArray()+ return clownface({+ _context: [...matched._context, more._context],+ })
Is this the correct way to merge multiple clownface contexts?
I use this way to combine all potential matching operations for the property candidates
comment created time in 2 days
Pull request review commentzazuko/hydra-box
failing cases for property operations
function factory ({ loader }) { return async (req, res, next) => { let resources = await loader.forClassOperation(req.hydra.term) + if (resources.length > 1) {+ return next(new Error(`no unique resource found for: <${req.hydra.term.value}>`))+ }+ if (resources.length === 0) { resources = await loader.forPropertyOperation(req.hydra.term)- }+ res.locals.hydra.resourceCandidates = resources - if (resources.length > 1) {- return next(new Error(`no unique resource found for: <${req.hydra.term.value}>`))+ debug('Multiple resource candidates found')+ return next()
Does not error immediately but instead set the potential "property operation" candidates to be filtered by the operation middleware
comment created time in 2 days
Pull request review commentzazuko/hydra-box
failing cases for property operations
function middleware (api, { baseIriFromRequest, loader, store, middleware = {} } throw new Error('no loader or store provided') } - if (middleware.resource) {- router.use(waitFor(init, () => middleware.resource))- }- router.use(waitFor(init, () => operation(api)))+ router.use(waitFor(init, () => operation(api, middleware.resource)))
I moved the resource middleware inside the operation because the resource handler above may not set a single req.hydra.resource.
comment created time in 2 days
Pull request review commentzazuko/hydra-box
failing cases for property operations
+<http://localhost:9000/category/rdf> <http://www.w3.org/1999/02/22-rdf-syntax-ns#type> <http://localhost:9000/api/schema/Category> .++<http://localhost:9000/category/rdf> <http://localhost:9000/api/schema/post> <http://localhost:9000/post/3> .
post/3 used with two properties. Will give 405 when requested with a method supported by neither property
comment created time in 2 days
Pull request review commentzazuko/hydra-box
failing cases for property operations
+<http://localhost:9000/category/csvw> <http://www.w3.org/1999/02/22-rdf-syntax-ns#type> <http://localhost:9000/api/schema/Category> .++<http://localhost:9000/category/csvw> <http://localhost:9000/api/schema/post> <http://localhost:9000/post/2> .
post/2 used only once here, will 404
comment created time in 2 days
Pull request review commentzazuko/hydra-box
failing cases for property operations
<comments> a hydra:Link; hydra:supportedOperation <comment#post>.++<Category> a hydra:Class ;+ hydra:supportedOperation+ <category#get>;+ hydra:supportedProperty [+ hydra:property <post>+ ] ;+ hydra:supportedProperty [+ hydra:property <pinned-post>+ ]+.
I added Category class with those two properties to test the behavior of resources only used as objects of those properties
comment created time in 2 days
push eventzazuko/hydra-box
commit sha cc7a448fb8b9c6f882f6326464b5bfc47e8e0577
refactor: extract and combine
push time in 2 days
push eventzazuko/hydra-box
commit sha 6219c08e021f376b7e58661887f4bb1f5ba0befe
refactor: remove commented out code
push time in 2 days
push eventzazuko/hydra-box
commit sha 2bd27c4389668780c39a993192da09f4fa1c5c30
test: update e2e scenarios
push time in 2 days
push eventzazuko/hydra-box
commit sha 8b6acfe221697ca9d61cc9685ea7be49c239877b
fix: more appropriate responses to negative result
push time in 2 days
push eventtpluscode/settings-repository
commit sha 29a2ab9a827b77620d664e804ffa0465081b0413
WS-2020.2.2 <[email protected] Update filetypes.xml
push time in 2 days
push eventtpluscode/settings-repository
commit sha 97597d5801dd8332c3a48109282956e4bc144027
WS-2020.2.2 <tomaszpluskiewicz@tomaszs-mbp Update find.xml
commit sha b6c47ee34c4c2440b191aaac420cc8a1c9a7d37c
WS-2020.2.2 <tomaszpluskiewicz@tomaszs-mbp Update find.xml
commit sha b5c34fd87bca8564800747c2019a319edd27e9af
WS-2020.2.2 <tomaszpluskiewicz@tomaszs-mbp Update find.xml
commit sha 51e4eb2dffa8ae6d32cf98b5594b1d6ea8d2f61c
WS-2020.2.2 <tomaszpluskiewicz@tomaszs-mbp Update find.xml
commit sha d1d038c67c7f796dde90194092a8755088819c88
WS-2020.2.2 <tomaszpluskiewicz@tomaszs-mbp Update find.xml
commit sha 7f0ddeaa3e1b84e44c2059e976f663cf806f775a
WS-2020.2.2 <tomaszpluskiewicz@tomaszs-mbp Update find.xml
push time in 2 days
issue openedzazuko/hydra-box
Unexpected responses from property objects with no operations
I created draft PR #86 which presents two issues with handling of property objects
Resource used as quad object but has no operation
Consider the <resource/bar> resource.
graph <resource/foo> {
  <resource/bar> rdf:seeOther <resource/bar>
}
Trying to perform an operation on it returns 405 which can be a little unexpected for object usage.
- is found but only as object and without any supported operation it should return
404
Resource used multiple times as quad object
Consider <resource/bar> again.
graph <resource/foo> {
  <resource/foo> rdf:seeOther <resource/bar>
}

graph <resource/baz> {
  <resource/foo> rdf:seeOther <resource/bar>
}
A resource which is found as object of multiple relations will cause a 500 response.
If a resource if found only as quad object:
- and has no supported operations, it should return
404 - and does not have an operation with matching
method, it should return405
created time in 2 days
push eventzazuko/cube-creator
commit sha 1a020f2adcc52e29843c9aa36f02b7fb910de525
refactor: rename project#cube to project#cubeGraph
push time in 2 days
PR opened zazuko/cube-creator


Fixes #100 by importing barnard59 cube schema steps
Notable changes (or semi-changes):
- The pipeline assumes a virtual column on table which has produce
?observation cc:cube ?cubetriples.- They are filtered out in the end.
- The
?cubeobject of those triples is used to construct theobservationSetIDs
- This will have the impact that a cube project will have to allow multiple cubes
- Cube as template means that we will not know the cube URIs up front; they will have to extracted from the result graph
- Instead I added
cc:cubeGraphproperty for the project to direct the result into that named graph
pr created time in 2 days
push eventzazuko/cube-creator
commit sha 23eba5db96a95a7fc0c4757a147eed40ccf15788
feat: produce cube using new schema from the pipeline
push time in 2 days
Pull request review commentzazuko/cube-creator
+import { GraphPointer } from 'clownface'+import { schema, rdf } from '@tpluscode/rdf-ns-builders'+import { cc } from '@cube-creator/core/namespace'+import { ResourceStore } from '../../ResourceStore'+import * as id from '../identifiers'+import { resourceStore } from '../resources'+import { NamedNode } from 'rdf-js'++interface CreateTableCommand {+ tableCollection: GraphPointer+ resource: GraphPointer+ store?: ResourceStore+}++export async function createTable({+ tableCollection,+ resource,+ store = resourceStore(),+}: CreateTableCommand): Promise<GraphPointer> {+ const label = resource.out(schema.name)+ if (!label?.term) {+ throw new Error('schema:name missing from the payload')+ }++ const csvMapping = tableCollection.out(cc.csvMapping)+ if (!csvMapping?.term) {+ throw new Error('cc:csvMapping missing from the payload')+ }++ if (!tableCollection?.term) {
You sure? Do check again
comment created time in 2 days
Pull request review commentzazuko/cube-creator
+import { GraphPointer } from 'clownface'+import { schema, rdf } from '@tpluscode/rdf-ns-builders'+import { cc } from '@cube-creator/core/namespace'+import { ResourceStore } from '../../ResourceStore'+import * as id from '../identifiers'+import { resourceStore } from '../resources'+import { NamedNode } from 'rdf-js'++interface CreateTableCommand {+ tableCollection: GraphPointer
tableCollection: GraphPointer<NamedNode>
comment created time in 2 days
Pull request review commentzazuko/cube-creator
+import { GraphPointer } from 'clownface'+import { schema, rdf } from '@tpluscode/rdf-ns-builders'+import { cc } from '@cube-creator/core/namespace'+import { ResourceStore } from '../../ResourceStore'+import * as id from '../identifiers'+import { resourceStore } from '../resources'+import { NamedNode } from 'rdf-js'++interface CreateTableCommand {+ tableCollection: GraphPointer+ resource: GraphPointer+ store?: ResourceStore+}++export async function createTable({+ tableCollection,+ resource,+ store = resourceStore(),+}: CreateTableCommand): Promise<GraphPointer> {+ const label = resource.out(schema.name)+ if (!label?.term) {+ throw new Error('schema:name missing from the payload')+ }++ const csvMapping = tableCollection.out(cc.csvMapping)+ if (!csvMapping?.term) {+ throw new Error('cc:csvMapping missing from the payload')+ }++ if (!tableCollection?.term) {+ throw new Error('Resource is not a valid tableCollection')+ }++ const table = await store+ .createMember(tableCollection.term as NamedNode, id.table(csvMapping.term, label.term.value))
.createMember(tableCollection.term, id.table(csvMapping.term, label.term.value))
This will also be unnecessary when you change the interface typing
comment created time in 2 days
push eventzazuko/cube-creator
commit sha eb20ac6cf70a820c216dd2c0a75ca1eb5bc338d4
refactor: inject function to load resource types
push time in 2 days
Pull request review commentzazuko/cube-creator
+import { GraphPointer } from 'clownface'+import { schema, rdf } from '@tpluscode/rdf-ns-builders'+import { cc } from '@cube-creator/core/namespace'+import { ResourceStore } from '../../ResourceStore'+import * as id from '../identifiers'+import { resourceStore } from '../resources'+import { NamedNode } from 'rdf-js'++interface CreateTableCommand {+ tableCollection: GraphPointer+ resource: GraphPointer+ store?: ResourceStore+}++export async function createTable({+ tableCollection,+ resource,+ store = resourceStore(),+}: CreateTableCommand): Promise<GraphPointer> {+ const label = resource.out(schema.name)+ if (!label?.term) {+ throw new Error('schema:name missing from the payload')+ }++ const csvMapping = tableCollection.out(cc.csvMapping)+ if (!csvMapping?.term) {+ throw new Error('cc:csvMapping missing from the payload')+ }
Ah shoot, I only looked at the error message where I understood as payload === request body
comment created time in 2 days