








dagster-io/dagster 1955
A Python library for building data applications: ETL, ML, Data Pipelines, and more.
sryza/aas 1402
Code to accompany Advanced Analytics with Spark from O'Reilly Media
Source material for Data Science for Telecom Tutorial at Strata Singapore 2015
Repo for experiments on pyspark and sklearn
Simple Spark Application
Calculating Value at Risk with Spark
Simple Spark app that reads and writes Avro data
Exploring CalTrans PEMS freeway data
Thesis in Distributed Combinatorial Optimization
.files, including ~/.osx — sensible hacker defaults for OS X
issue commentdagster-io/dagster
https://dagster.phacility.com/D4113

comment created time in 4 days
push eventdagster-io/dagster
commit sha 59fa6a43e59946d9a887753c94f6ec33bfacd4e2
[docs] dagit overview Summary: {F230565} {F230566} {F230569} {F230570} {F230571} {F230572} Test Plan: manual inspection Reviewers: nate, sashank, yuhan Reviewed By: nate Differential Revision: https://dagster.phacility.com/D4113
push time in 4 days
issue openeddagster-io/dagster
In pipeline definition page, "Explode composites" overlaps selection box
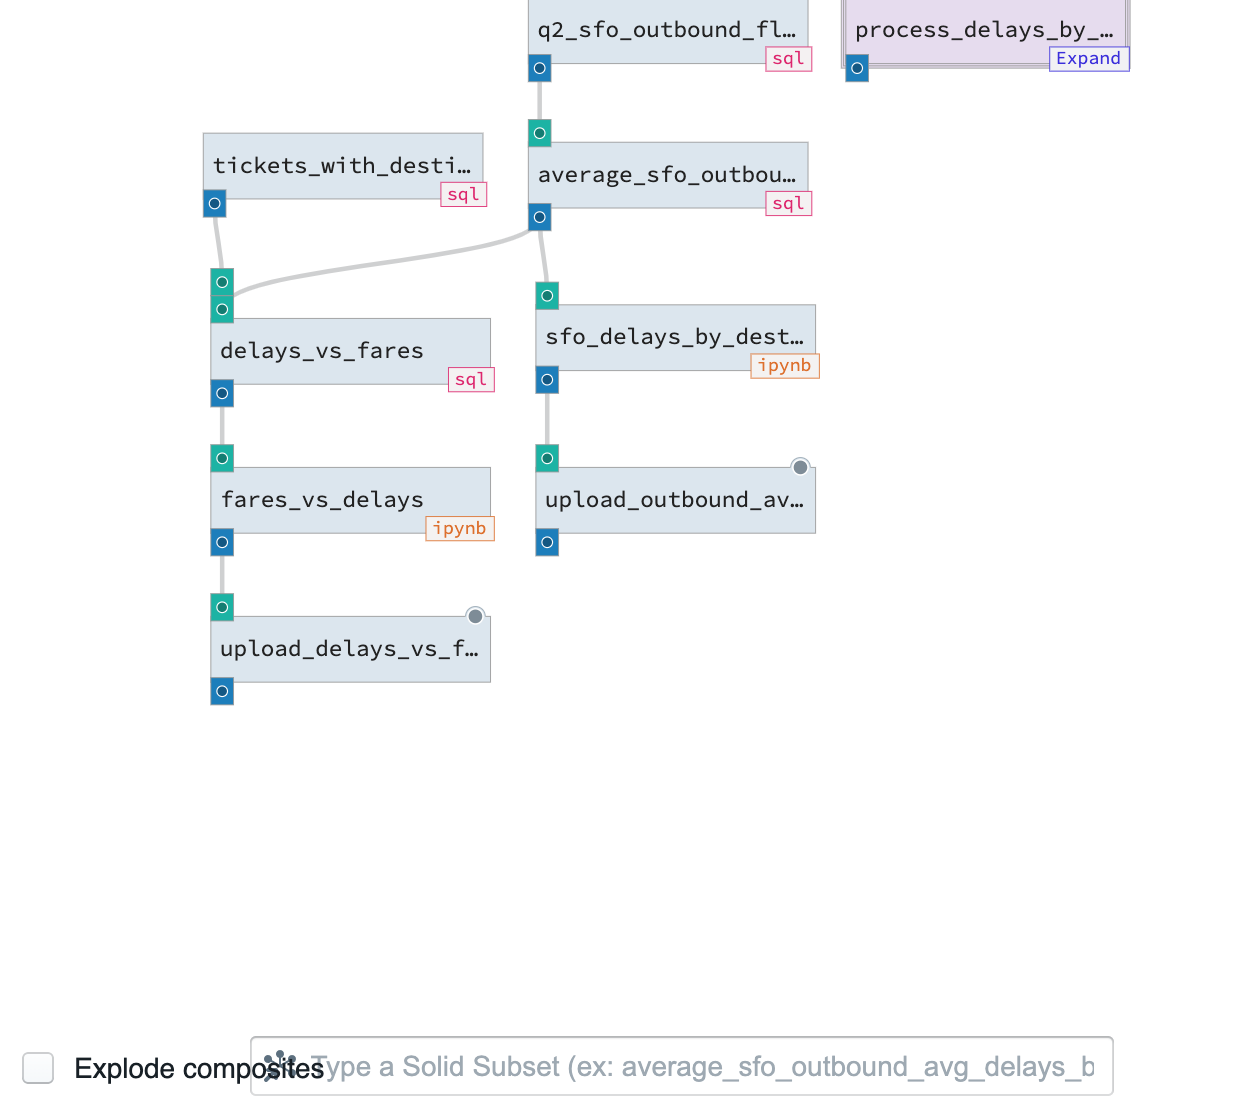
created time in 4 days
issue closeddagster-io/dagster
Revisit existence of dagster-aws CLI
Ideally replace w/ blessed ECS-based deployment strategy
closed time in 4 days
natekupp
issue commentdagster-io/dagster
Revisit existence of dagster-aws CLI
We removed this
comment created time in 4 days
issue commentdagster-io/dagster
Add Spark YARN configs to Spark config
When I initially filed this, I didn't realize that we had an escape hatch with these configs. I'm going to close this.

comment created time in 4 days
issue closeddagster-io/dagster
Add Spark YARN configs to Spark config
We generate the Spark config spec by parsing the Spark documentation: https://raw.githubusercontent.com/apache/spark/v2.4.4/docs/configuration.md.
However, not all Spark configs are on that page. YARN configs live in https://raw.githubusercontent.com/apache/spark/v2.4.4/docs/running-on-yarn.md / https://spark.apache.org/docs/latest/running-on-yarn.html
Parsing that as well would enable setting YARN-specific Spark configs.
closed time in 4 days
sryza
issue closeddagster-io/dagster
rewrite tutorial for 0.8.0 to omit `@scheduler`, `repository.yaml`
closed time in 4 days
mgasner
issue commentdagster-io/dagster
rewrite tutorial for 0.8.0 to omit `@scheduler`, `repository.yaml`
I checked the tutorial, and it seems like @daily_schedule is used instead of @schedule, and I couldn't find any references to repository.yaml. I'm going to close this - feel free to reopen if I missed something.
comment created time in 4 days
push eventdagster-io/dagster
commit sha 5a180928c2a3ea4fd1fec1c3ed2721f0e451ca12
explain what devs must do after editing api.proto Test Plan: none Reviewers: prha, max Reviewed By: prha Differential Revision: https://dagster.phacility.com/D4095
push time in 5 days
push eventdagster-io/dagster
commit sha 706b25b5eaf5ad09b92016e72b28a76730220182
remove deprecated "config" args that have been replaced with "config_schema" Summary: There's some open discussion on config_field, so I didn't touch that yet: https://github.com/dagster-io/dagster/issues/2724. Test Plan: bk Reviewers: schrockn, alangenfeld Reviewed By: alangenfeld Differential Revision: https://dagster.phacility.com/D4055
push time in 5 days
issue commentdagster-io/dagster
CLI repo-loading errors are less legible than before
https://dagster.phacility.com/D4087
comment created time in 5 days
push eventdagster-io/dagster
commit sha 374eb5e89e47ee2e133f30af272bd95e012e11d7
pull back dagster_type arg to asset materializations Summary: There's still a lot up in the air around how we think about the relationship between assets, types, and adjacent concepts. Based on discussion with @schrockn, we decided it's too early to start drawing lines between them before we have more clarity on how they fit together. This pulls back the materialization / dagster_type changes so we can work this stuff out without thrashing our users. Revert "modifying metadata with prefix" This reverts commit 011049bc875a8316cb12f0bbcd786287bb7c5b19. Revert "Adding type info to materializations as metadata" This reverts commit 36037b9a56aa22ee354c0171e925c95911fa25f5. Test Plan: bk Reviewers: schrockn, max, leoeer, prha Reviewed By: schrockn Differential Revision: https://dagster.phacility.com/D4056
push time in 6 days
issue openeddagster-io/dagster
CLI repo-loading errors are less legible than before
I had a bug in a python module that I was trying to load a repo from to execute on the CLI. The actual error that's useful is buried inside the message of the DagsterIPCProtocolError, difficult to understand because the "\n"s don't render as newlines.
Traceback (most recent call last):
  File "/Users/sryza/dagster/python_modules/dagster/dagster/api/utils.py", line 11, in execute_command_in_subprocess
    subprocess.check_output(parts, stderr=subprocess.STDOUT)
  File "/Users/sryza/.pyenv/versions/3.6.8/lib/python3.6/subprocess.py", line 356, in check_output
    **kwargs).stdout
  File "/Users/sryza/.pyenv/versions/3.6.8/lib/python3.6/subprocess.py", line 438, in run
    output=stdout, stderr=stderr)
subprocess.CalledProcessError: Command '['/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/bin/python3.6', '-m', 'dagster', 'api', 'list_repositories', '/var/folders/df/2_jxd7dx073273d_mpywh4080000gn/T/tmpf_t93t_j', '/var/folders/df/2_jxd7dx073273d_mpywh4080000gn/T/tmpyyx3_gjt']' returned non-zero exit status 1.

During handling of the above exception, another exception occurred:

Traceback (most recent call last):
  File "/Users/sryza/.pyenv/versions/dagster-3.6.8/bin/dagster", line 11, in <module>
    load_entry_point('dagster', 'console_scripts', 'dagster')()
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/__init__.py", line 38, in main
    cli(obj={})  # pylint:disable=E1123
  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 764, in __call__
    return self.main(*args, **kwargs)
  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 717, in main
    rv = self.invoke(ctx)
  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 1137, in invoke
    return _process_result(sub_ctx.command.invoke(sub_ctx))
  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 1137, in invoke
    return _process_result(sub_ctx.command.invoke(sub_ctx))
  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 956, in invoke
    return ctx.invoke(self.callback, **ctx.params)
  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 555, in invoke
    return callback(*args, **kwargs)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/pipeline.py", line 262, in pipeline_execute_command
    return _logged_pipeline_execute_command(config, preset, mode, DagsterInstance.get(), kwargs)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/core/telemetry.py", line 89, in wrap
    result = f(*args, **kwargs)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/pipeline.py", line 290, in _logged_pipeline_execute_command
    result = execute_execute_command(env, kwargs, mode, tags)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/pipeline.py", line 297, in execute_execute_command
    external_pipeline = get_external_pipeline_from_kwargs(cli_args, instance)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/cli_target.py", line 404, in get_external_pipeline_from_kwargs
    external_repo = get_external_repository_from_kwargs(kwargs, instance)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/cli_target.py", line 367, in get_external_repository_from_kwargs
    repo_location = get_repository_location_from_kwargs(kwargs, instance)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/cli_target.py", line 335, in get_repository_location_from_kwargs
    workspace = get_workspace_from_kwargs(kwargs, instance)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/cli_target.py", line 198, in get_workspace_from_kwargs
    return workspace_from_load_target(created_workspace_load_target(kwargs), instance)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/cli_target.py", line 168, in workspace_from_load_target
    user_process_api=python_user_process_api,
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/load.py", line 253, in location_handle_from_python_file
    attribute=attribute,
  File "/Users/sryza/dagster/python_modules/dagster/dagster/api/list_repositories.py", line 17, in sync_list_repositories
    attribute=attribute,
  File "/Users/sryza/dagster/python_modules/dagster/dagster/api/utils.py", line 32, in execute_unary_api_cli_command
    execute_command_in_subprocess(parts)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/api/utils.py", line 14, in execute_command_in_subprocess
    "Error when executing API command {cmd}: {output}".format(cmd=e.cmd, output=e.output)
dagster.serdes.ipc.DagsterIPCProtocolError: Error when executing API command ['/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/bin/python3.6', '-m', 'dagster', 'api', 'list_repositories', '/var/folders/df/2_jxd7dx073273d_mpywh4080000gn/T/tmpf_t93t_j', '/var/folders/df/2_jxd7dx073273d_mpywh4080000gn/T/tmpyyx3_gjt']: b'/Users/sryza/dagster/python_modules/libraries/dagster-pandas/dagster_pandas/data_frame.py:190: UserWarning: Using create_dagster_pandas_dataframe_type for dataframe types is deprecated,\n     and is planned to be removed in a future version (tentatively 0.10.0).\n     Please use create_structured_dataframe_type instead.\n  Please use create_structured_dataframe_type instead."""\nTraceback (most recent call last):\n  File "/Users/sryza/.pyenv/versions/3.6.8/lib/python3.6/runpy.py", line 193, in _run_module_as_main\n    "__main__", mod_spec)\n  File "/Users/sryza/.pyenv/versions/3.6.8/lib/python3.6/runpy.py", line 85, in _run_code\n    exec(code, run_globals)\n  File "/Users/sryza/dagster/python_modules/dagster/dagster/__main__.py", line 3, in <module>\n    main()\n  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/__init__.py", line 38, in main\n    cli(obj={})  # pylint:disable=E1123\n  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 764, in __call__\n    return self.main(*args, **kwargs)\n  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 717, in main\n    rv = self.invoke(ctx)\n  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 1137, in invoke\n    return _process_result(sub_ctx.command.invoke(sub_ctx))\n  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 1137, in invoke\n    return _process_result(sub_ctx.command.invoke(sub_ctx))\n  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 956, in invoke\n    return ctx.invoke(self.callback, **ctx.params)\n  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 555, in invoke\n    return callback(*args, **kwargs)\n  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/api.py", line 115, in command\n    output = check.inst(fn(args), output_cls)\n  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/api.py", line 140, in list_repositories_command\n    loadable_targets = get_loadable_targets(python_file, module_name, working_directory, attribute)\n  File "/Users/sryza/dagster/python_modules/dagster/dagster/grpc/utils.py", line 20, in get_loadable_targets\n    else loadable_targets_from_python_file(python_file, working_directory)\n  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/autodiscovery.py", line 11, in loadable_targets_from_python_file\n    loaded_module = load_python_file(python_file, working_directory)\n  File "/Users/sryza/dagster/python_modules/dagster/dagster/core/code_pointer.py", line 88, in load_python_file\n    return import_module_from_path(module_name, python_file)\n  File "/Users/sryza/dagster/python_modules/dagster/dagster/seven/__init__.py", line 110, in import_module_from_path\n    spec.loader.exec_module(module)\n  File "<frozen importlib._bootstrap_external>", line 678, in exec_module\n  File "<frozen importlib._bootstrap>", line 219, in _call_with_frames_removed\n  File "examples/legacy_examples/dagster_examples/simple_lakehouse/simple_lakehouse.py", line 189, in <module>\n    from dagster_examples.simple_lakehouse.daily_temperature_high_diffs import (\n  File "/Users/sryza/dagster/examples/legacy_examples/dagster_examples/__init__.py", line 31, in <module>\n    @repository\n  File "/Users/sryza/dagster/python_modules/dagster/dagster/core/definitions/decorators/repository.py", line 225, in repository\n    return _Repository()(name)\n  File "/Users/sryza/dagster/python_modules/dagster/dagster/core/definitions/decorators/repository.py", line 23, in __call__\n    repository_definitions = fn()\n  File "/Users/sryza/dagster/examples/legacy_examples/dagster_examples/__init__.py", line 37, in legacy_examples\n    + get_lakehouse_pipelines()\n  File "/Users/sryza/dagster/examples/legacy_examples/dagster_examples/__init__.py", line 17, in get_lakehouse_pipelines\n    from dagster_examples.simple_lakehouse.pipelines import simple_lakehouse_pipeline\n  File "/Users/sryza/dagster/examples/legacy_examples/dagster_examples/simple_lakehouse/pipelines.py", line 7, in <module>\n    from dagster_examples.simple_lakehouse.simple_lakehouse import simple_lakehouse\nImportError: cannot import name \'simple_lakehouse\'\n'
What it used to look like in 0.8.5:
Traceback (most recent call last):
  File "/Users/sryza/.pyenv/versions/dagster-3.6.8/bin/dagster", line 11, in <module>
    load_entry_point('dagster', 'console_scripts', 'dagster')()
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/__init__.py", line 40, in main
    cli(obj={})  # pylint:disable=E1123
  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 764, in __call__
    return self.main(*args, **kwargs)
  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 717, in main
    rv = self.invoke(ctx)
  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 1137, in invoke
    return _process_result(sub_ctx.command.invoke(sub_ctx))
  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 1137, in invoke
    return _process_result(sub_ctx.command.invoke(sub_ctx))
  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 956, in invoke
    return ctx.invoke(self.callback, **ctx.params)
  File "/Users/sryza/.pyenv/versions/3.6.8/envs/dagster-3.6.8/lib/python3.6/site-packages/click/core.py", line 555, in invoke
    return callback(*args, **kwargs)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/core/telemetry.py", line 76, in wrap
    result = f(*args, **kwargs)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/pipeline.py", line 321, in pipeline_execute_command
    result = execute_execute_command(env, kwargs, mode, tags)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/pipeline.py", line 327, in execute_execute_command
    external_pipeline = get_external_pipeline_from_kwargs(cli_args)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/cli_target.py", line 287, in get_external_pipeline_from_kwargs
    external_repo = get_external_repository_from_kwargs(kwargs)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/cli_target.py", line 251, in get_external_repository_from_kwargs
    repo_location = get_repository_location_from_kwargs(kwargs)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/cli_target.py", line 220, in get_repository_location_from_kwargs
    workspace = get_workspace_from_kwargs(kwargs)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/cli_target.py", line 104, in get_workspace_from_kwargs
    return workspace_from_load_target(created_workspace_load_target(kwargs))
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/cli_target.py", line 93, in workspace_from_load_target
    [location_handle_from_python_file(load_target.python_file, load_target.attribute)]
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/load.py", line 145, in location_handle_from_python_file
    else loadable_targets_from_python_file(python_file)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/cli/workspace/autodiscovery.py", line 12, in loadable_targets_from_python_file
    loaded_module = load_python_file(python_file)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/core/code_pointer.py", line 73, in load_python_file
    return import_module_from_path(module_name, python_file)
  File "/Users/sryza/dagster/python_modules/dagster/dagster/seven/__init__.py", line 88, in import_module_from_path
    spec.loader.exec_module(module)
  File "<frozen importlib._bootstrap_external>", line 678, in exec_module
  File "<frozen importlib._bootstrap>", line 219, in _call_with_frames_removed
  File "examples/legacy_examples/dagster_examples/simple_lakehouse/lakehouse.py", line 8, in <module>
    from lakehouse import Lakehouse, TypeStoragePolicy
ImportError: cannot import name 'Lakehouse'
created time in 6 days
issue closeddagster-io/dagster
Add lint rule for errant print statements
@prha has boldly led us into the world of custom linting (see https://dagster.phacility.com/D3893)
We recently pushed a bug where are an errant print statement broke a user. In the leave no trace/replace your divots/fix things systematically spirit, let us add a lint rule to catch future instances of this.
This would be we would force a pylint directive for any legitimate print statement, which I think is the right tradeoff.
closed time in 6 days
schrockn
push eventdagster-io/dagster
commit sha 83a8e303d0f1efc3a34b3bc88bfc208b7e836fc2
Add dask dataframe (#2758) * add data_frame * add tests * fix `description` * fix tests
push time in 6 days
PR merged dagster-io/dagster
Add dask dataframe as a DagsterType.

pr closed time in 6 days
pull request commentdagster-io/dagster
Thanks for this contribution, David!
comment created time in 6 days
Pull request review commentdagster-io/dagster
commands = !windows: /bin/bash -c '! pip list --exclude-editable | grep -e dagster -e dagit' coverage erase echo -e "--- \033[0;32m:pytest: Running tox tests\033[0m"+ python -m pip install "dask[dataframe]" --upgrade+ pip install pyarrow
@natekupp - is tox.ini the right place to include pyarrow if we want it for tests, but not to be a dependency for the package?
comment created time in 11 days
Pull request review commentdagster-io/dagster
+import dask.dataframe as dd++from dagster import (+ Any,+ AssetMaterialization,+ Bool,+ DagsterInvariantViolationError,+ DagsterType,+ Enum,+ EnumValue,+ EventMetadataEntry,+ Field,+ Int,+ Permissive,+ String,+ TypeCheck,+ check,+ dagster_type_loader,+ dagster_type_materializer,+)+from dagster.config.field_utils import Selector++WriteCompressionTextOptions = Enum(+ 'WriteCompressionText', [EnumValue('gzip'), EnumValue('bz2'), EnumValue('xz'),],+)++EngineParquetOptions = Enum(+ 'EngineParquet', [EnumValue('auto'), EnumValue('fastparquet'), EnumValue('pyarrow'),],+)+++def dict_without_keys(ddict, *keys):+ return {key: value for key, value in ddict.items() if key not in set(keys)}+++@dagster_type_materializer(+ Selector(+ {+ 'csv': Permissive(+ {+ 'path': Field(+ Any,+ is_required=True,+ description="str or list, Path glob indicating the naming scheme for the output files",+ ),+ 'single_file': Field(+ Bool,+ is_required=False,+ description="Whether to save everything into a single CSV file. Under the single file mode, each partition is appended at the end of the specified CSV file. Note that not all filesystems support the append mode and thus the single file mode, especially on cloud storage systems such as S3 or GCS. A warning will be issued when writing to a file that is not backed by a local filesystem.",+ ),+ 'encoding': Field(+ String,+ is_required=False,+ description="A string representing the encoding to use in the output file, defaults to 'ascii' on Python 2 and 'utf-8' on Python 3.",+ ),+ 'mode': Field(+ String, is_required=False, description="Python write mode, default 'w'",+ ),+ 'compression': Field(+ WriteCompressionTextOptions,+ is_required=False,+ description="a string representing the compression to use in the output file, allowed values are 'gzip', 'bz2', 'xz'",+ ),+ 'compute': Field(+ Bool,+ is_required=False,+ description="If true, immediately executes. If False, returns a set of delayed objects, which can be computed at a later time.",+ ),+ 'storage_options': Field(+ Permissive(),+ is_required=False,+ description="Parameters passed on to the backend filesystem class.",+ ),+ 'header_first_partition_only': Field(+ Bool,+ is_required=False,+ description="If set to `True`, only write the header row in the first output file. By default, headers are written to all partitions under the multiple file mode (`single_file` is `False`) and written only once under the single file mode (`single_file` is `True`). It must not be `False` under the single file mode.",+ ),+ 'compute_kwargs': Field(+ Permissive(),+ is_required=False,+ description="Options to be passed in to the compute method",+ ),+ }+ ),+ 'parquet': Permissive(+ {+ 'path': Field(+ Any,+ is_required=True,+ description="str or pathlib.Path, Destination directory for data. Prepend with protocol like ``s3://`` or ``hdfs://`` for remote data.",+ ),+ 'engine': Field(+ EngineParquetOptions,+ is_required=False,+ description="{'auto', 'fastparquet', 'pyarrow'}, default 'auto' Parquet library to use. If only one library is installed, it will use that one; if both, it will use 'fastparquet'.",+ ),+ 'compression': Field(+ Any,+ is_required=False,+ description="str or dict, optional Either a string like ``'snappy'`` or a dictionary mapping column names to compressors like ``{'name': 'gzip', 'values': 'snappy'}``. The default is ``'default'``, which uses the default compression for whichever engine is selected.",+ ),+ 'write_index': Field(+ Bool,+ is_required=False,+ description="Whether or not to write the index. Defaults to True.",+ ),+ 'append': Field(+ Bool,+ is_required=False,+ description="If False (default), construct data-set from scratch. If True, add new row-group(s) to an existing data-set. In the latter case, the data-set must exist, and the schema must match the input data.",+ ),+ 'ignore_divisions': Field(+ Bool,+ is_required=False,+ description="If False (default) raises error when previous divisions overlap with the new appended divisions. Ignored if append=False.",+ ),+ 'partition_on': Field(+ list,+ is_required=False,+ description="Construct directory-based partitioning by splitting on these fields values. Each dask partition will result in one or more datafiles, there will be no global groupby.",+ ),+ 'storage_options': Field(+ Permissive(),+ is_required=False,+ description="Key/value pairs to be passed on to the file-system backend, if any.",+ ),+ 'write_metadata_file': Field(+ Bool,+ is_required=False,+ description="Whether to write the special '_metadata' file.",+ ),+ 'compute': Field(+ Bool,+ is_required=False,+ description="If True (default) then the result is computed immediately. If False then a ``dask.delayed`` object is returned for future computation.",+ ),+ 'compute_kwargs': Field(+ Permissive(),+ is_required=False,+ description="Options to be passed in to the compute method.",+ ),+ }+ ),+ 'hdf': Permissive(+ {+ 'path': Field(+ Any,+ is_required=True,+ description="str or pathlib.Path, Path to a target filename. Supports strings, ``pathlib.Path``, or any object implementing the ``__fspath__`` protocol. May contain a ``*`` to denote many filenames.",+ ),+ 'key': Field(+ String,+ is_required=True,+ description="Datapath within the files. May contain a ``*`` to denote many locations",+ ),+ 'compute': Field(+ Bool,+ is_required=False,+ description="Whether or not to execute immediately. If False then this returns a ``dask.Delayed`` value.",+ ),+ 'scheduler': Field(+ String,+ is_required=False,+ description="The scheduler to use, like 'threads' or 'processes'",+ ),+ }+ ),+ 'json': Permissive(+ {+ 'path': Field(+ Any,+ is_required=True,+ description="str or list, Location to write to. If a string, and there are more than one partitions in df, should include a glob character to expand into a set of file names, or provide a ``name_function=`` parameter. Supports protocol specifications such as ``'s3://'``.",+ ),+ 'encoding': Field(+ String,+ is_required=False,+ description="default is 'utf-8', The text encoding to implement, e.g., 'utf-8'",+ ),+ 'errors': Field(+ String,+ is_required=False,+ description="default is 'strict', how to respond to errors in the conversion (see ``str.encode()``)",+ ),+ 'storage_options': Field(+ Permissive(),+ is_required=False,+ description="Passed to backend file-system implementation",+ ),+ 'compute': Field(+ Bool,+ is_required=False,+ description="If true, immediately executes. If False, returns a set of delayed objects, which can be computed at a later time.",+ ),+ 'compute_kwargs': Field(+ Permissive(),+ is_required=False,+ description="Options to be passed in to the compute method",+ ),+ 'compression': Field(+ String, is_required=False, description="String like 'gzip' or 'xz'.",+ ),+ },+ ),+ 'sql': Permissive(+ {+ 'name': Field(String, is_required=True, description="Name of SQL table",),+ 'uri': Field(+ String,+ is_required=True,+ description="Full sqlalchemy URI for the database connection",+ ),+ 'schema': Field(+ String,+ is_required=False,+ description="Specify the schema (if database flavor supports this). If None, use default schema.",+ ),+ 'if_exists': Field(+ String,+ is_required=False,+ description="""+ {'fail', 'replace', 'append'}, default 'fail'"+ How to behave if the table already exists.+ * fail: Raise a ValueError.+ * replace: Drop the table before inserting new values.+ * append: Insert new values to the existing table.+ """,+ ),+ 'index': Field(+ Bool,+ is_required=False,+ description="default is True, Write DataFrame index as a column. Uses `index_label` as the column name in the table.",+ ),+ 'index_label': Field(+ Any,+ is_required=False,+ description="str or sequence, default None Column label for index column(s). If None is given (default) and `index` is True, then the index names are used. A sequence should be given if the DataFrame uses MultiIndex.",+ ),+ 'chunksize': Field(+ Int,+ is_required=False,+ description="Specify the number of rows in each batch to be written at a time. By default, all rows will be written at once",+ ),+ 'dtype': Field(+ Any,+ is_required=False,+ description="dict or scalar, Specifying the datatype for columns. If a dictionary is used, the keys should be the column names and the values should be the SQLAlchemy types or strings for the sqlite3 legacy mode. If a scalar is provided, it will be applied to all columns.",+ ),+ 'method': Field(+ String,+ is_required=False,+ description="""+ {None, 'multi', callable}, default None+ Controls the SQL insertion clause used:+ * None : Uses standard SQL ``INSERT`` clause (one per row).+ * 'multi': Pass multiple values in a single ``INSERT`` clause.+ * callable with signature ``(pd_table, conn, keys, data_iter)``.+ Details and a sample callable implementation can be found in the+ section :ref:`insert method <io.sql.method>`.+ """,+ ),+ 'compute': Field(+ Bool,+ is_required=False,+ description="default is True, When true, call dask.compute and perform the load into SQL; otherwise, return a Dask object (or array of per-block objects when parallel=True)",+ ),+ 'parallel': Field(+ Bool,+ is_required=False,+ description="default is False, When true, have each block append itself to the DB table concurrently. This can result in DB rows being in a different order than the source DataFrame's corresponding rows. When false, load each block into the SQL DB in sequence.",+ ),+ },+ ),+ },+ )+)+def dataframe_materializer(_context, config, dask_df):+ check.inst_param(dask_df, 'dask_df', dd.DataFrame)+ file_type, file_options = list(config.items())[0]+ path = file_options.get('path')++ if file_type == 'csv':+ dask_df.to_csv(path, **dict_without_keys(file_options, 'path'))+ elif file_type == 'parquet':+ dask_df.to_parquet(path, **dict_without_keys(file_options, 'path'))+ elif file_type == 'hdf':+ dask_df.to_hdf(path, **dict_without_keys(file_options, 'path'))+ elif file_type == 'json':+ dask_df.to_json(path, **dict_without_keys(file_options, 'path'))+ elif file_type == 'sql':+ dask_df.to_sql(**file_options)+ else:+ check.failed('Unsupported file_type {file_type}'.format(file_type=file_type))++ return AssetMaterialization.file(path)+++@dagster_type_loader(+ Selector(+ {+ 'csv': Permissive(+ {+ 'path': Field(+ Any,+ is_required=True,+ description="str or list, Absolute or relative filepath(s). Prefix with a protocol like `s3://` to read from alternative filesystems. To read from multiple files you can pass a globstring or a list of paths, with the caveat that they must all have the same protocol.",+ ),+ 'blocksize': Field(+ Any,+ is_required=False,+ description="str or int or None, Number of bytes by which to cut up larger files. Default value is computed based on available physical memory and the number of cores, up to a maximum of 64MB. Can be a number like 64000000` or a string like ``'64MB'. If None, a single block is used for each file.",+ ),+ 'sample': Field(+ Int,+ is_required=False,+ description="Number of bytes to use when determining dtypes.",+ ),+ 'assume_missing': Field(+ Bool,+ is_required=False,+ description="If True, all integer columns that aren’t specified in `dtype` are assumed to contain missing values, and are converted to floats. Default is False.",+ ),+ 'storage_options': Field(+ Permissive(),+ is_required=False,+ description="Extra options that make sense for a particular storage connection, e.g. host, port, username, password, etc.",+ ),+ 'include_path_column': Field(+ Any,+ is_required=False,+ description="bool or str, Whether or not to include the path to each particular file. If True a new column is added to the dataframe called path. If str, sets new column name. Default is False.",+ ),+ }+ ),+ 'parquet': Permissive(+ {+ 'path': Field(+ Any,+ is_required=True,+ description="str or list, Source directory for data, or path(s) to individual parquet files. Prefix with a protocol like s3:// to read from alternative filesystems. To read from multiple files you can pass a globstring or a list of paths, with the caveat that they must all have the same protocol.",+ ),+ 'columns': Field(+ Any,+ is_required=False,+ description="str or list or None (default), Field name(s) to read in as columns in the output. By default all non-index fields will be read (as determined by the pandas parquet metadata, if present). Provide a single field name instead of a list to read in the data as a Series.",+ ),+ 'filters': Field(
Is there a way for users to populate this using Dagster's config system? I don't think we support a tuple type, which means I don't think we can satisfy what dask is expecting. It could make sense to leave this out for now if there's significant complexity required to make it work.
comment created time in 11 days
Pull request review commentdagster-io/dagster
+import dask.dataframe as dd++from dagster import (+ Any,+ AssetMaterialization,+ Bool,+ DagsterInvariantViolationError,+ DagsterType,+ Enum,+ EnumValue,+ EventMetadataEntry,+ Field,+ Int,+ Permissive,+ String,+ TypeCheck,+ check,+ dagster_type_loader,+ dagster_type_materializer,+)+from dagster.config.field_utils import Selector++WriteCompressionTextOptions = Enum(+ 'WriteCompressionText', [EnumValue('gzip'), EnumValue('bz2'), EnumValue('xz'),],+)++EngineParquetOptions = Enum(+ 'EngineParquet', [EnumValue('auto'), EnumValue('fastparquet'), EnumValue('pyarrow'),],+)+++def dict_without_keys(ddict, *keys):+ return {key: value for key, value in ddict.items() if key not in set(keys)}+++@dagster_type_materializer(+ Selector(+ {+ 'csv': Permissive(+ {+ 'path': Field(+ Any,+ is_required=True,+ description="str or list, Path glob indicating the naming scheme for the output files",+ ),+ 'single_file': Field(+ Bool,+ is_required=False,+ description="Whether to save everything into a single CSV file. Under the single file mode, each partition is appended at the end of the specified CSV file. Note that not all filesystems support the append mode and thus the single file mode, especially on cloud storage systems such as S3 or GCS. A warning will be issued when writing to a file that is not backed by a local filesystem.",+ ),+ 'encoding': Field(+ String,+ is_required=False,+ description="A string representing the encoding to use in the output file, defaults to 'ascii' on Python 2 and 'utf-8' on Python 3.",+ ),+ 'mode': Field(+ String, is_required=False, description="Python write mode, default 'w'",+ ),+ 'compression': Field(+ WriteCompressionTextOptions,+ is_required=False,+ description="a string representing the compression to use in the output file, allowed values are 'gzip', 'bz2', 'xz'",+ ),+ 'compute': Field(+ Bool,+ is_required=False,+ description="If true, immediately executes. If False, returns a set of delayed objects, which can be computed at a later time.",+ ),+ 'storage_options': Field(+ Permissive(),+ is_required=False,+ description="Parameters passed on to the backend filesystem class.",+ ),+ 'header_first_partition_only': Field(+ Bool,+ is_required=False,+ description="If set to `True`, only write the header row in the first output file. By default, headers are written to all partitions under the multiple file mode (`single_file` is `False`) and written only once under the single file mode (`single_file` is `True`). It must not be `False` under the single file mode.",+ ),+ 'compute_kwargs': Field(+ Permissive(),+ is_required=False,+ description="Options to be passed in to the compute method",+ ),+ }+ ),+ 'parquet': Permissive(+ {+ 'path': Field(+ Any,+ is_required=True,+ description="str or pathlib.Path, Destination directory for data. Prepend with protocol like ``s3://`` or ``hdfs://`` for remote data.",+ ),+ 'engine': Field(+ EngineParquetOptions,+ is_required=False,+ description="{'auto', 'fastparquet', 'pyarrow'}, default 'auto' Parquet library to use. If only one library is installed, it will use that one; if both, it will use 'fastparquet'.",+ ),+ 'compression': Field(+ Any,+ is_required=False,+ description="str or dict, optional Either a string like ``'snappy'`` or a dictionary mapping column names to compressors like ``{'name': 'gzip', 'values': 'snappy'}``. The default is ``'default'``, which uses the default compression for whichever engine is selected.",+ ),+ 'write_index': Field(+ Bool,+ is_required=False,+ description="Whether or not to write the index. Defaults to True.",+ ),+ 'append': Field(+ Bool,+ is_required=False,+ description="If False (default), construct data-set from scratch. If True, add new row-group(s) to an existing data-set. In the latter case, the data-set must exist, and the schema must match the input data.",+ ),+ 'ignore_divisions': Field(+ Bool,+ is_required=False,+ description="If False (default) raises error when previous divisions overlap with the new appended divisions. Ignored if append=False.",+ ),+ 'partition_on': Field(+ list,+ is_required=False,+ description="Construct directory-based partitioning by splitting on these fields values. Each dask partition will result in one or more datafiles, there will be no global groupby.",+ ),+ 'storage_options': Field(+ Permissive(),+ is_required=False,+ description="Key/value pairs to be passed on to the file-system backend, if any.",+ ),+ 'write_metadata_file': Field(+ Bool,+ is_required=False,+ description="Whether to write the special '_metadata' file.",+ ),+ 'compute': Field(+ Bool,+ is_required=False,+ description="If True (default) then the result is computed immediately. If False then a ``dask.delayed`` object is returned for future computation.",+ ),+ 'compute_kwargs': Field(+ Permissive(),+ is_required=False,+ description="Options to be passed in to the compute method.",+ ),+ }+ ),+ 'hdf': Permissive(+ {+ 'path': Field(+ Any,+ is_required=True,+ description="str or pathlib.Path, Path to a target filename. Supports strings, ``pathlib.Path``, or any object implementing the ``__fspath__`` protocol. May contain a ``*`` to denote many filenames.",+ ),+ 'key': Field(+ String,+ is_required=True,+ description="Datapath within the files. May contain a ``*`` to denote many locations",+ ),+ 'compute': Field(+ Bool,+ is_required=False,+ description="Whether or not to execute immediately. If False then this returns a ``dask.Delayed`` value.",+ ),+ 'scheduler': Field(+ String,+ is_required=False,+ description="The scheduler to use, like 'threads' or 'processes'",+ ),+ }+ ),+ 'json': Permissive(+ {+ 'path': Field(+ Any,+ is_required=True,+ description="str or list, Location to write to. If a string, and there are more than one partitions in df, should include a glob character to expand into a set of file names, or provide a ``name_function=`` parameter. Supports protocol specifications such as ``'s3://'``.",+ ),+ 'encoding': Field(+ String,+ is_required=False,+ description="default is 'utf-8', The text encoding to implement, e.g., 'utf-8'",+ ),+ 'errors': Field(+ String,+ is_required=False,+ description="default is 'strict', how to respond to errors in the conversion (see ``str.encode()``)",+ ),+ 'storage_options': Field(+ Permissive(),+ is_required=False,+ description="Passed to backend file-system implementation",+ ),+ 'compute': Field(+ Bool,+ is_required=False,+ description="If true, immediately executes. If False, returns a set of delayed objects, which can be computed at a later time.",+ ),+ 'compute_kwargs': Field(+ Permissive(),+ is_required=False,+ description="Options to be passed in to the compute method",+ ),+ 'compression': Field(+ String, is_required=False, description="String like 'gzip' or 'xz'.",+ ),+ },+ ),+ 'sql': Permissive(+ {+ 'name': Field(String, is_required=True, description="Name of SQL table",),+ 'uri': Field(+ String,+ is_required=True,+ description="Full sqlalchemy URI for the database connection",+ ),+ 'schema': Field(+ String,+ is_required=False,+ description="Specify the schema (if database flavor supports this). If None, use default schema.",+ ),+ 'if_exists': Field(+ String,+ is_required=False,+ description="""+ {'fail', 'replace', 'append'}, default 'fail'"+ How to behave if the table already exists.+ * fail: Raise a ValueError.+ * replace: Drop the table before inserting new values.+ * append: Insert new values to the existing table.+ """,+ ),+ 'index': Field(+ Bool,+ is_required=False,+ description="default is True, Write DataFrame index as a column. Uses `index_label` as the column name in the table.",+ ),+ 'index_label': Field(+ Any,+ is_required=False,+ description="str or sequence, default None Column label for index column(s). If None is given (default) and `index` is True, then the index names are used. A sequence should be given if the DataFrame uses MultiIndex.",+ ),+ 'chunksize': Field(+ Int,+ is_required=False,+ description="Specify the number of rows in each batch to be written at a time. By default, all rows will be written at once",+ ),+ 'dtype': Field(+ Any,+ is_required=False,+ description="dict or scalar, Specifying the datatype for columns. If a dictionary is used, the keys should be the column names and the values should be the SQLAlchemy types or strings for the sqlite3 legacy mode. If a scalar is provided, it will be applied to all columns.",+ ),+ 'method': Field(+ String,+ is_required=False,+ description="""+ {None, 'multi', callable}, default None+ Controls the SQL insertion clause used:+ * None : Uses standard SQL ``INSERT`` clause (one per row).+ * 'multi': Pass multiple values in a single ``INSERT`` clause.+ * callable with signature ``(pd_table, conn, keys, data_iter)``.+ Details and a sample callable implementation can be found in the+ section :ref:`insert method <io.sql.method>`.+ """,+ ),+ 'compute': Field(+ Bool,+ is_required=False,+ description="default is True, When true, call dask.compute and perform the load into SQL; otherwise, return a Dask object (or array of per-block objects when parallel=True)",+ ),+ 'parallel': Field(+ Bool,+ is_required=False,+ description="default is False, When true, have each block append itself to the DB table concurrently. This can result in DB rows being in a different order than the source DataFrame's corresponding rows. When false, load each block into the SQL DB in sequence.",+ ),+ },+ ),+ },+ )+)+def dataframe_materializer(_context, config, dask_df):+ check.inst_param(dask_df, 'dask_df', dd.DataFrame)+ file_type, file_options = list(config.items())[0]+ path = file_options.get('path')++ if file_type == 'csv':+ dask_df.to_csv(path, **dict_without_keys(file_options, 'path'))+ elif file_type == 'parquet':+ dask_df.to_parquet(path, **dict_without_keys(file_options, 'path'))+ elif file_type == 'hdf':+ dask_df.to_hdf(path, **dict_without_keys(file_options, 'path'))+ elif file_type == 'json':+ dask_df.to_json(path, **dict_without_keys(file_options, 'path'))+ elif file_type == 'sql':+ dask_df.to_sql(**file_options)+ else:+ check.failed('Unsupported file_type {file_type}'.format(file_type=file_type))++ return AssetMaterialization.file(path)+++@dagster_type_loader(+ Selector(+ {+ 'csv': Permissive(+ {+ 'path': Field(+ Any,+ is_required=True,+ description="str or list, Absolute or relative filepath(s). Prefix with a protocol like `s3://` to read from alternative filesystems. To read from multiple files you can pass a globstring or a list of paths, with the caveat that they must all have the same protocol.",
These should remain within 100 characters.
comment created time in 11 days
Pull request review commentdagster-io/dagster
commands = !windows: /bin/bash -c '! pip list --exclude-editable | grep -e dagster -e dagit' coverage erase echo -e "--- \033[0;32m:pytest: Running tox tests\033[0m"+ python -m pip install "dask[dataframe]" --upgrade+ pip install pyarrow
If I understand correctly, pyarrow is only required if someone wants to use their parquet reader. If that's the case, I think it would be best to leave it out of the dependencies, and users can include it in their dependencies if needed.
comment created time in 11 days
issue openeddagster-io/dagster
lint docstrings to ensure google-style formatting
E.g. make sure that we do
Returns:
    str: Some words
instead of
Returns (str):
    some words
Maybe we can use https://github.com/terrencepreilly/darglint
created time in 16 days